Newsletter, guides
LLM API retry logic: Backoff, jitter and what to skip
LLM API retry logic for production agents. Which errors to retry, backoff with jitter, retry-after, SDK retry defaults and retry budgets, with Python code.
The user sent a malformed prompt and your agent got back a 400 Bad Request. Your retry loop did not check the status code. It retried the call with exponential backoff until it ran out of attempts. The user waited half a minute for an error they could have seen at once, and your logs filled with noise.
LLM API retry logic is an error-handling policy that resends a failed model call by classifying the error first, then waiting with backoff and jitter. Only transient errors get a retry. This guide covers which errors to retry, the retries your SDK already does, the backoff math, and how agent retry logic differs from retrying a single call.
Key takeaways
- Retry only transient errors: connection failures, timeouts, 408, 409, 429 rate limits and 5xx server or overload errors.
- Never retry 400, 401, 403, 404, 413 or 422, or a 429 caused by a spend cap or exhausted quota. Those fail the same way every time.
- The Anthropic and OpenAI Python SDKs already retry transient errors twice by default. Set
max_retries=0when you add your own retry layer, or the attempts multiply. - Use exponential backoff with jitter, honor the
retry-afterheader, and cap both the attempts and the total time. - In agents, retry at one layer only, keep a retry budget per run, and never re-run a tool with side effects because a later model call failed.
Why do naive retry loops make LLM errors worse?
Because “retry on any exception” treats every failure as transient. Three failure modes follow:
- Retrying deterministic errors. A bad request, a wrong key or a spend cap fails the same way on every attempt. Retries only delay the error the user needs to see.
- No backoff. A tight loop on a rate-limited call hits the limit again at once, and the throttling continues.
- No jitter. If many clients retry on the same schedule, they hit the API in waves and trip the limit together again.
A correct policy sorts errors before it waits. Transient errors get bounded retries with backoff and jitter. Deterministic errors are raised on the first attempt.

Which LLM API errors should you retry?
Retry errors that can succeed on the next attempt without any change on your side. Raise everything else on the first attempt.
| Retry with backoff | Raise at once |
|---|---|
| Connection errors and client timeouts | 400 bad request, including context too long |
| 408 request timeout, 409 conflict | 401 authentication, 403 permission |
429 rate limit with a retry-after header |
404 not found, 413 request too large, 422 |
| 500, 502, 503, 504 | 429 or 400 from a spend cap or exhausted quota |
| 529 overloaded (Anthropic) | Content-policy refusals of the same prompt |
The tricky row is 429. Most 429s are rate limits that clear in seconds. On Anthropic, a 429 from the monthly spend cap has no retry-after header and carries error_code: enforced_spend_limit_reached. A spend limit you set yourself returns 400 instead. OpenAI’s error guide says retrying billing, spend or quota errors will not restore access. Retrying either kind only burns time.
Does the SDK already retry LLM API calls?
Yes. The official Anthropic and OpenAI Python SDKs retry connection errors, 408, 409, 429 and 5xx responses twice by default, with a short exponential backoff. Anthropic’s docs say its SDK also honors the retry-after header.
That default is enough for many apps. Tune it with max_retries on the client or per request. Trouble starts when you wrap the SDK in your own retry decorator and keep the default. Four attempts in your layer times three in the SDK is twelve calls for one request.
Pick one layer that owns retries. If you write your own policy, set max_retries=0 on the client.
How do you build LLM API retry logic in Python?
Use Tenacity with a predicate that classifies the exception, a wait function that reads retry-after, and two stop conditions. The predicate is the part most code gets wrong.
# filename: app/llm/retry.py
# description: One retry layer for Claude API calls: classify, honor retry-after, cap attempts and time.
from anthropic import Anthropic, APIConnectionError, APIStatusError
from tenacity import (
    RetryCallState, retry, retry_if_exception, stop_after_attempt,
    stop_after_delay, wait_exponential_jitter,
)

client = Anthropic(max_retries=0)  # this module owns retries, so the SDK does not retry too

RETRYABLE_STATUS = {408, 409, 429, 500, 502, 503, 504, 529}


def _is_retryable(exc: BaseException) -> bool:
    if isinstance(exc, APIConnectionError):  # includes APITimeoutError
        return True
    if isinstance(exc, APIStatusError):
        details = ((exc.body or {}).get("error") or {}).get("details") or {}
        if details.get("error_code") == "enforced_spend_limit_reached":
            return False  # spend cap: fails until the cap resets
        return exc.status_code in RETRYABLE_STATUS
    return False


_backoff = wait_exponential_jitter(initial=1, max=30, jitter=2)


def wait_retry_after(state: RetryCallState) -> float:
    exc = state.outcome.exception()
    response = getattr(exc, "response", None)
    header = response.headers.get("retry-after") if response is not None else None
    if header:
        try:
            return min(float(header), 60.0)
        except ValueError:
            pass  # HTTP-date form: fall back to backoff
    return _backoff(state)


@retry(
    retry=retry_if_exception(_is_retryable),
    stop=stop_after_attempt(4) | stop_after_delay(60),
    wait=wait_retry_after,
    reraise=True,
)
def call_llm(**kwargs):
    return client.messages.create(**kwargs)
Four decisions matter here. retry_if_exception(_is_retryable) routes every error through the classifier. Do not use retry_if_exception_type(APIStatusError): BadRequestError subclasses APIStatusError, so that would retry every 4xx. stop_after_attempt(4) | stop_after_delay(60) caps both the tries and the wall-clock time. reraise=True raises the original SDK exception on the final failure, not a Tenacity wrapper.
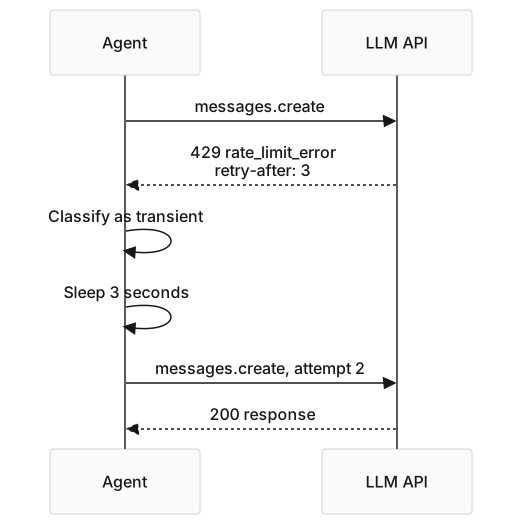
We ran this policy against stubbed errors. A 400 raised after one call. A 429 with retry-after: 3 slept 3 seconds and then succeeded. A spend-cap 429 raised at once, and four 529s stopped after three backoff sleeps.
Why does jitter matter so much?
Because without jitter, failures synchronize. If many clients hit a rate limit at the same moment, plain exponential backoff sends them all back at 1, 2 and 4 seconds. The provider sees a spike at each step instead of a spread-out load.
Marc Brooker’s AWS analysis compared backoff with no jitter, equal jitter and full jitter. No jitter did the most work and took the longest. Full jitter picks a random sleep between zero and the capped exponential value. Tenacity calls that wait_random_exponential. wait_exponential_jitter, used above, adds a random amount on top of the exponential value instead. Both spread retries out.
How do you choose timeouts and retries without amplifying load?
Set a timeout per call, cap total retry time, and retry at one layer only. The Google SRE book shows why: if every layer of a stack retries, the attempts multiply into a combinatorial explosion during an outage.
The SRE book also describes two budgets. A per-request budget allows up to three attempts. A per-client budget retries only while retries stay under 10 percent of requests. With that cap, load during a partial outage grows to about 1.1 times normal instead of nearly 3 times. Track the retry ratio in your client and stop retrying when it passes the budget.
For timeouts, both SDKs default to 10 minutes. Set a shorter timeout on calls with small outputs, and stream long generations instead of raising the timeout. A stream that fails after the first tokens is not covered by SDK retries. Anthropic sends errors after a 200 response as error events in the stream, so your code must restart the turn.
How should agent retry logic differ from a single call?
An agent run is many model calls and tool calls in a loop, so retries need state. Retry the step that failed, not the whole run, and keep every result that already succeeded.
- Checkpoint tool results. If a model call fails after a tool sent an email or charged a card, retrying the step must not run that tool again. Store each tool result before the next model call. With LangGraph, a checkpointer does this, as in LangGraph persistence and thread models.
- Make side-effect tools idempotent. Pass an idempotency key, such as the run ID plus step number, so a repeated call is a no-op.
- Keep a retry budget per run. Count retries across all steps and fail the run when it passes a cap. A run that needs many retries is usually hitting a real outage.
- Open a circuit breaker on persistent failure. When a provider keeps failing, stop calling it and switch to a fallback model or a clear error. The AI chatbot system design guide has a minimal breaker.
What should you log on every retry?
Log enough to debug the retry, and nothing that leaks data:
- Error class and status code, so you know which failure you hit.
- Attempt number and wait time, so you can see whether backoff works.
- Provider request ID and your trace ID. Anthropic returns a
request-idheader on every response, and the Python SDK exposes it as_request_id.
Do not log the full prompt on every retry. Prompts carry user data and secrets. Export retry counts and final status as metrics, as in Prometheus metrics for agentic AI, and alert when the retry ratio climbs.
What to do next
- Find every LLM call wrapper. If it retries on any exception, fix it first.
- Choose one retry layer. If it is your own code, set
max_retries=0on the SDK client. - Add a classifier that retries connection errors, 408, 409, 429, 5xx and 529, and raises the rest.
- Treat spend-cap and quota errors as fatal, and alert on them.
- Honor
retry-after, use backoff with jitter, and cap attempts and total time. - Test it: send a malformed prompt and confirm the 400 raises after one call.
- Track the retry ratio per client and per agent run, and stop retrying above your budget.
Frequently asked questions
Which LLM API errors should I retry?
Retry transient errors: connection failures, timeouts, 408, 409, 429 rate limits, 5xx server errors and Anthropic’s 529 overloaded error. Do not retry 400, 401, 403, 404, 413 or 422, and do not retry a 429 or 400 caused by a spend cap or exhausted quota. Those fail the same way every time, so retries only waste time and hide the real error from the user.
Why am I seeing excessive LLM API retries?
The usual cause is two retry layers. The Anthropic and OpenAI SDKs retry transient errors twice by default. If you wrap the call in Tenacity or a loop, each of your attempts runs the SDK’s retries too. Set max_retries=0 on the client when you own the policy. Also check that your retry predicate excludes 4xx errors, because a broad exception filter retries them all.
How do I implement retry logic for LLM API failures?
Start with the SDK’s built-in retries and tune max_retries. When you need more control, disable SDK retries and use Tenacity. Write a predicate that classifies the exception by status code. Add a wait function that honors retry-after and falls back to exponential backoff with jitter. Then cap the attempts and the total time, and re-raise the original exception at the end.
How many retries are enough for an LLM API call?
Three to four total attempts cover most transient failures, with a time cap of about a minute for interactive requests. The Google SRE book uses three attempts per request. If calls still fail after that, the provider is likely having an outage. A circuit breaker and a fallback model help more than extra retries at that point.
What is exponential backoff with jitter?
It is a wait strategy where each retry waits longer than the last, plus a random offset. The growing wait gives an overloaded service time to recover. The random offset stops many clients from retrying at the same moment. AWS’s analysis found that backoff with full jitter does far less work than backoff without jitter when many clients compete.
Sources
- Claude API errors and Rate limits, Anthropic docs, checked October 2026: status codes including 529, mid-stream error events, the
retry-afterheader and the spend-cap 429. - Python SDK, Anthropic docs, checked October 2026: default retries of 2 for connection errors, 408, 409, 429 and 5xx,
max_retries, and the 10-minute default timeout. - Error codes, OpenAI API docs, checked October 2026: follow
Retry-After, and retrying billing, spend or quota errors does not restore access. - Exponential backoff and jitter, Marc Brooker, AWS Architecture Blog, March 2015: no jitter versus equal and full jitter.
- Handling overload, Google, Site Reliability Engineering: per-request and per-client retry budgets, and retrying at one layer only.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997