Should this be an agent? It is the first design question in any AI feature, and I think too many teams let their framework answer it for them. When τ-bench was published, Sierra tested 12 agents on customer service tasks, and even the best stayed under 50% average success1.
Whoever decides what runs next, your code or the model, sets what the system costs, how it fails and how you debug it. That is the whole of AI agents vs workflows.
If your code decides, you have a workflow. If the model decides, you have an agent. If one model hands work to other models, you have a multi-agent system.
Make the workflow your default and let the agent earn its place
The workflow is the default because the difference is one of control, not intelligence. Anthropic draws the line in two sentences: workflows are systems where models and tools are orchestrated through predefined code paths2, and agents are systems where the model directs its own process and tool use2.
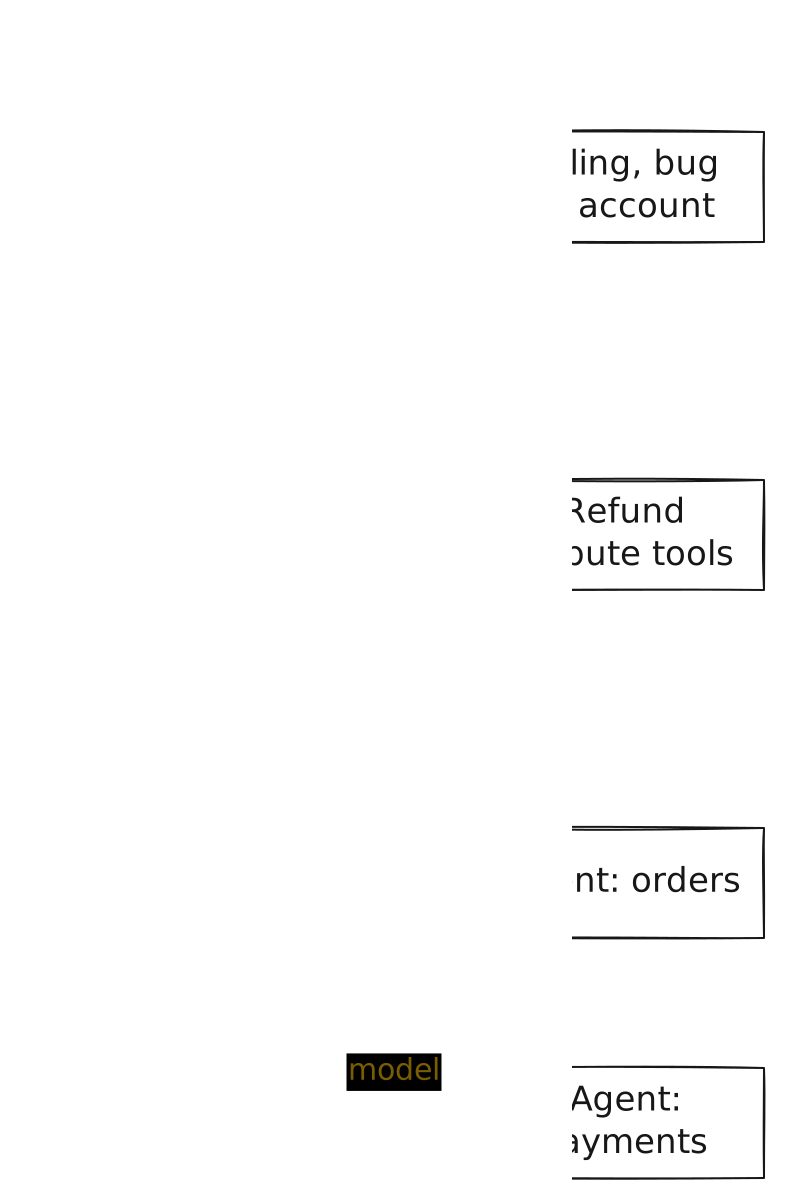
Follow the support ticket through all three. In the workflow, one model call labels the ticket and a plain match statement picks the next step, so billing, bug and account tickets each take a fixed path. In the single agent, the model chooses which tool to call next and when to stop. With several agents, a lead model also chooses which other models to wake.
Anthropic's advice, from building with customers, is to find the simplest solution possible and only add complexity when needed2. The most successful implementations they saw used simple, composable patterns rather than complex frameworks2. OpenAI's guide makes the same call one level up: maximize a single agent's capabilities first3.
The agent earns its place where the path cannot be written down. Anthropic reserves agents for open-ended problems where the number of steps is hard or impossible to predict and a fixed path cannot be hardcoded2. In the ticket system only a refund dispute fits: the agent may need the order, then the payments, then the delivery record, in an order no rule predicts.
The router is where you keep that boundary honest. Structured outputs guarantee schema-compliant responses through constrained decoding4, except, the same docs warn, on a refusal or a max_tokens cutoff. So the code checks stop_reason first, hands those to a person, and the match only sees labels your code knows.
triage.pyfrom typing import Literal
from pydantic import BaseModel
from settings import client, MODEL
from routes import billing_reply, file_bug, account_reply
from refund_agent import refund_agent
from handoff import hand_to_person
class Label(BaseModel):
kind: Literal["billing", "bug", "account", "refund_dispute"]
summary: str
def classify(ticket: str) -> Label | None:
response = client.messages.parse(
model=MODEL,
max_tokens=1024,
system="Label this support ticket and summarise it in one sentence.",
messages=[{"role": "user", "content": ticket}],
output_format=Label,
)
if response.stop_reason != "end_turn": # a refusal or a max_tokens cutoff
return None
return response.parsed_output
def handle_ticket(ticket: str):
label = classify(ticket) # the model judges inside one step
if label is None:
return hand_to_person(ticket, [])
match label.kind: # your code picks the next step
case "billing":
return billing_reply(ticket, label)
case "bug":
return file_bug(ticket, label)
case "account":
return account_reply(ticket, label)
case "refund_dispute":
return refund_agent(ticket, label) # the one step the model steersThe same split decides how you debug it. Each fixed case is a function you can unit test alone, retry as a single step, and explain to an auditor from its input and output. The refund agent is the one branch whose path is chosen at run time, so it is the one you debug by reading its trace.
When someone proposes another agent step in review, ask which case it replaces and which real ticket showed the fixed path failing.