Newsletter, guides
Tool calling for LLMs: How it works, with Python code
What tool calling is, how the request, execute and answer loop works, and Python code for OpenAI and Claude tool calls with Pydantic schemas.

An LLM on its own is a brain in a jar. It can talk, reason and write code, but it cannot check the weather, query your database or book a flight. Ask it “What’s the weather in San Francisco right now?” and the best it can do is guess or apologize.
Tool calling is an LLM API feature that lets a model act on the outside world by returning a structured request to run one of your functions. The model never runs anything itself. It picks a tool and fills in arguments that match a JSON schema you supplied. Your code runs the function and feeds the result back. This guide builds that loop in Python with Pydantic and shows the OpenAI and Claude formats side by side. It also covers how tool calling relates to function calling, MCP and agents.
Key takeaways
- Tool calling lets an LLM request a function call as structured JSON; your application runs the function and sends the result back.
- One tool call is a round trip: the model asks, your code executes, and a second model call turns the result into an answer.
- Tool calling and function calling are the same mechanism. OpenAI used “function calling” first, and most providers now say “tools”.
- A Pydantic model can generate the JSON schema for a tool and validate the arguments the model returns.
- An agent is tool calling inside a loop that runs until the model stops asking for tools or a step limit is hit.
- MCP does not replace tool calling. It is a protocol for discovering and running tools that a model still calls through tool calling.
What is tool calling?
Tool calling is how an LLM asks your application to run code. You send the model a list of tools, each with a name, a description and a JSON schema for its arguments. When a tool would help, the model replies with a tool call instead of text.
A tool call is a small JSON object: the tool’s name, the arguments, and an ID that links the call to its result. “Tool calls” in an API response are those objects. Your code reads them, runs the matching functions and returns the outputs tagged with the same IDs.
The split of work is the whole idea. The LLM is the router that decides what to call. Your application is the executor that decides whether and how to run it.
How does tool calling work?
Tool calling works as a loop between your app and the model. Your app sends the question with the tool schemas, and the model returns a tool call. Your app runs the function, and a second request sends the result back for the final answer.
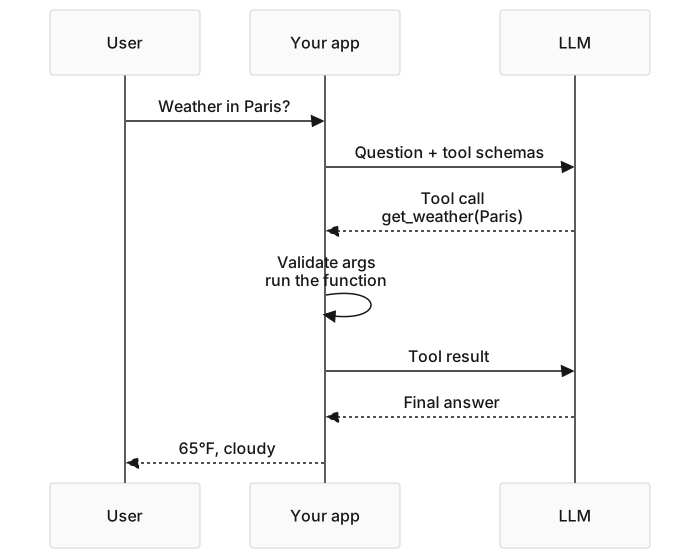
The model only ever sees text and JSON. It never touches your network, your database or your shell. That is why the executor side is where you put validation, permissions and timeouts.
How do you build tool calling in Python?
You define the tool’s arguments as a Pydantic model, describe the tool to the API, then handle the tool call and send the result back. The code below uses the OpenAI Responses API, which OpenAI’s newest models require for tool calling.
Step 1: define the tool’s contract with Pydantic
# filename: main.py
# description: The argument schema for a get_weather tool.
from typing import Literal

from pydantic import BaseModel, Field

class GetWeather(BaseModel):
    """Arguments for the get_weather tool."""
    city: str = Field(..., description="The city, e.g. 'San Francisco' or 'Tokyo'")
    unit: Literal["celsius", "fahrenheit"] = Field(
        "celsius", description="Temperature unit for the answer"
    )
The description fields are part of the prompt. The model reads them to decide what to put in each argument. A Literal type becomes an enum in the schema, so the model sees the only allowed values.
Step 2: describe the tool to the API
# main.py (continued)
from openai import OpenAI

client = OpenAI()  # reads OPENAI_API_KEY from the environment

tools = [
    {
        "type": "function",
        "name": "get_weather",
        "description": "Gets the current weather for a city.",
        "parameters": GetWeather.model_json_schema(),
    }
]
GetWeather.model_json_schema() turns the class into the JSON schema the API expects. The schema and your Python types now come from one place, so they cannot drift apart.
Step 3: make the first call and read the tool call
# main.py (continued)
MODEL = "gpt-5-mini"  # any current OpenAI model with tool calling

input_list = [{"role": "user", "content": "What's the weather in Paris in fahrenheit?"}]

response = client.responses.create(
    model=MODEL,
    input=input_list,
    tools=tools,
    tool_choice="auto",  # the model decides whether to call a tool
)
input_list += response.output  # keep the model's tool call in the history
The model does not answer with text. Its output holds a function_call item like this:
{
  "type": "function_call",
  "call_id": "call_abc123",
  "name": "get_weather",
  "arguments": "{\"city\": \"Paris\", \"unit\": \"fahrenheit\"}"
}
The model pulled “Paris” and “fahrenheit” out of the question and shaped them to match your schema. Note that arguments is a JSON string, not an object.
Step 4: validate the arguments and run the function
# main.py (continued)
import json

def get_weather(city: str, unit: str = "celsius") -> dict:
    """A mock weather lookup."""
    return {"temp": 65, "condition": "cloudy", "unit": unit}

for item in response.output:
    if item.type == "function_call" and item.name == "get_weather":
        args = GetWeather.model_validate_json(item.arguments)  # raises on bad input
        result = get_weather(args.city, args.unit)
        input_list.append(
            {
                "type": "function_call_output",
                "call_id": item.call_id,
                "output": json.dumps(result),
            }
        )
model_validate_json checks the arguments before anything runs. If the model sends a bad value, catch the validation error and return it as the tool output, so the model can retry.
Step 5: send the result back for the final answer
# main.py (continued)
final = client.responses.create(model=MODEL, input=input_list, tools=tools)
print(final.output_text)
The weather in Paris is currently 65°F and cloudy.
The second call carries the question, the model’s tool call and your tool output. The model turns that history into a plain answer.
How does tool calling differ between OpenAI and Claude?
The loop is identical; the field names differ. Both take a JSON schema per tool, return a structured call with an ID, and expect the result back tagged with that ID.
- Tool definition: OpenAI uses
parametersfor the schema. Claude’s Messages API usesinput_schema. - The call: OpenAI returns a
function_callitem withargumentsas a JSON string. Claude returns atool_usecontent block withinputas a parsed object, and setsstop_reasonto"tool_use". - The result: OpenAI takes a
function_call_outputitem with thecall_id. Claude takes atool_resultblock, with the matchingtool_use_id, inside a user message. - Older OpenAI code: the Chat Completions API nests the schema under a
functionkey and returns results as arole: "tool"message with atool_call_id.
Both providers support tool_choice to force or forbid a call, parallel tool calls in one turn, and a strict: true flag that makes calls match the schema exactly.
What is the difference between tool calling and function calling?
There is none. “Function calling” is the name OpenAI used when it launched the feature in 2023, and “tool calling” or “tool use” is the broader name most providers use now. OpenAI’s own docs still say function calling. Anthropic’s docs say tool use, “also called function calling”.
The word “tool” also covers tools the provider runs for you. Claude’s web search and code execution are server tools: Anthropic executes them and returns the results in the same response.
How is MCP different from tool calling?
MCP standardizes where tools come from. Tool calling is how the model asks for one. The Model Context Protocol defines how a client lists a server’s tools with tools/list and runs one with tools/call.
An MCP client takes the tools a server lists, passes their inputSchema to the model as ordinary tool definitions, and forwards the model’s tool calls to the server. So MCP sits on the executor side of the loop. For a hands-on build, see how to build a production MCP server.
What is programmatic tool calling?
Programmatic tool calling is a Claude API feature where the model writes code that calls your tools, instead of making one model round trip per call. The code runs in Anthropic’s code execution container. You opt a tool in with the allowed_callers field.
It helps when a task needs many tool calls whose raw results the model does not need to read. The script loops, filters and returns only the summary. Anthropic reports lower latency and fewer input tokens for multi-tool workflows.
When is one tool call not enough?
When the next step depends on the last result. “Book the hotel only if the flight is under $300” needs the flight price before the model can decide on the hotel. A single request and answer round trip cannot do that.
The fix is a loop. Keep calling the model, run every tool call it returns, and stop when it answers without a tool call. That loop is what people mean by an agent.

Always cap the loop with a step limit. A model that keeps calling tools without converging will otherwise run up cost forever. Once tools can change things, gate them the way the bash tool guide for coding agents gates shell commands. Wrap the model calls in the retry patterns for LLM API errors too.
What to do next
- Write one Pydantic model per tool, with a
descriptionon every field. - Generate each tool schema with
model_json_schema()instead of writing JSON by hand. - Validate every tool call with
model_validate_jsonbefore you run it, and return validation errors to the model as tool output. - Add a second tool and ask a question that needs both. Check that your loop handles several tool calls in one turn.
- Wrap the round trip in a loop with a step limit, then log every tool call and its result.
- Build the full agent with tool calling, memory and a dashboard in the AI mission control lab.
Frequently asked questions
What do tool calls mean?
Tool calls are structured requests an LLM returns when it wants your application to run a function. Each one names the tool, carries arguments that match the tool’s JSON schema, and has an ID. Your code runs the function and sends the result back with the same ID. The model then uses that result to continue or to write its final answer.
What is the difference between tool calling and function calling?
They are the same mechanism under two names. OpenAI introduced it as function calling in 2023, and most providers now call it tool calling or tool use. In every version, the model returns a structured request to run a function you defined, and your application executes it. Provider-hosted tools such as web search are why “tool” became the broader word.
Can an LLM call multiple tools at once?
Yes. Current OpenAI and Claude models can return several tool calls in one turn, for example a weather lookup and a product search for one question. Your code runs each call and returns every result with its matching ID. Both APIs let you turn this off: parallel_tool_calls: false on OpenAI, and disable_parallel_tool_use inside tool_choice on Claude.
Is tool calling the same as an AI agent?
No. Tool calling is one round trip: the model requests a function, your code runs it, and the model answers. An agent wraps that round trip in a loop, so the model can call tools again based on earlier results until the task is done. Every agent uses tool calling, but a single tool call is not an agent.
Why use Pydantic for tool calling?
Pydantic gives you one source of truth for a tool’s arguments. model_json_schema() generates the JSON schema the API needs, and field descriptions become instructions the model reads. model_validate_json() then checks the arguments the model sends back before your function runs. Your schema, your types and your validation stay in sync as the tool changes.
Sources
- Function calling, OpenAI, October 2026: the Responses API tool format,
function_call_output,tool_choice, parallel calls and strict mode. - Tool use with Claude, Anthropic, October 2026:
input_schema,tool_useandtool_resultblocks, client and server tools. - Programmatic tool calling, Anthropic, October 2026: tools called from code execution with
allowed_callers. - Tools, Model Context Protocol specification, July 2026:
tools/list,tools/callandinputSchema.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997
Or watch the recording: Build a Mission Control for AI Agents