Newsletter, guides
Bash tool for AI coding agents: Safe shell execution
Build a bash tool for a coding agent that is scoped and time-bounded, with an allowlist, a path guard, an output cap, human approval and a sandbox.
The moment you give a coding agent a run_bash tool, the job changes. You are no longer building a model that produces text. You are building a system that executes shell commands an LLM decided to run. One misread instruction or one confused loop, and the agent can delete files, open sockets, or run the wrong migration on the wrong database.
A bash tool is an agent tool that lets an LLM run shell commands by returning each command as a tool call for your application to execute. You cannot make it safe by trusting the model. You make it safe by designing the tool so dangerous commands fail, whatever the model asked for. This guide is the bash tool design I use for coding agents: the safe execution layers, the traps beginners fall into, and the sandbox that limits the blast radius when the model goes off the rails.
Key takeaways
- A bash tool runs whatever command the model returns, so treat every command as untrusted input.
- Pass a token list from
shlex.splittosubprocess.runand never useshell=Truein a tool the model controls. - An allowlist of binaries beats a denylist, but it is a tripwire, not a boundary:
pythonorfindon the list can still do damage. - Cap output, tier timeouts by binary, and resolve every file path against the workspace before the command runs.
- Require human approval for high-impact commands such as
git pushandgit reset --hard, even when the binary is allowed. - The real boundary is isolation: run the shell in a container, VM or OS sandbox as a least-privileged user.
Why can’t you just wrap subprocess.run?
Because a bare subprocess.run(command, shell=True) runs anything, including rm -rf on the wrong directory. An LLM that decides to “clean up the working directory” will eventually produce that string. The naive bash tool looks like this:
# filename: naive_bash.py
# description: The bash tool you should not ship. No timeout, no limits,
# no allowlist, no output cap. This will bite you within a week.
import subprocess

def run_bash(command: str) -> str:
    result = subprocess.run(command, shell=True, capture_output=True, text=True)
    return result.stdout + result.stderr
Several things are wrong. No timeout, so a runaway command hangs the agent forever. No output cap, so cat bigfile dumps megabytes into the LLM context and blows the token budget. No filter, so the model can run anything, including commands that break the host. And shell=True hands the string to a shell, so ;, && and $(...) all work.
That is fine for a laptop demo. It is not fine for anything you leave running unattended or wire into a production pipeline.
What does a safe bash tool look like?
A safe bash tool stacks small checks in front of the shell, each catching a different failure: parsing, an allowlist, a path guard, an approval gate, then a sandboxed run with a timeout and an output cap.

Every layer is useful on its own. Skipping one opens a hole. The core fits in about 30 lines.
# filename: safe_bash.py
# description: A bash tool with allowlist, timeout, scrubbed env, output cap,
# and structured results. Drop-in replacement for the naive version.
import shlex
import subprocess
from pathlib import Path

ALLOWED_BINARIES = {
    'ls', 'cat', 'head', 'tail', 'grep', 'find',
    'git', 'python', 'pytest', 'npm', 'node',
    'rg', 'fd', 'wc', 'echo', 'pwd',
}
MAX_OUTPUT_CHARS = 20_000
DEFAULT_TIMEOUT = 30

def run_bash(command: str, cwd: Path) -> dict:
    tokens = shlex.split(command)
    if not tokens or tokens[0] not in ALLOWED_BINARIES:
        return {'ok': False, 'error': f'binary not allowed: {tokens[0] if tokens else ""}'}

    try:
        result = subprocess.run(
            tokens,
            cwd=cwd,
            capture_output=True,
            text=True,
            timeout=DEFAULT_TIMEOUT,
            env={'PATH': '/usr/bin:/bin', 'HOME': str(cwd)},
        )
    except subprocess.TimeoutExpired:
        return {'ok': False, 'error': f'timeout after {DEFAULT_TIMEOUT}s'}

    return {
        'ok': result.returncode == 0,
        'exit_code': result.returncode,
        'stdout': result.stdout[:MAX_OUTPUT_CHARS],
        'stderr': result.stderr[:MAX_OUTPUT_CHARS],
        'truncated': len(result.stdout) > MAX_OUTPUT_CHARS,
    }
Read that line by line. shlex.split turns the command into tokens, so the allowlist checks the actual binary, not a substring of a longer string. subprocess.run takes the token list with no shell=True, so ;, && and | reach the program as plain arguments instead of chaining commands. The env dict strips the environment down to PATH and HOME, so secret env vars do not leak into child processes. The timeout and output cap protect against runaways and context blowups.
Note that capture_output still buffers the full output in memory before the slice. For commands that can print gigabytes, stream the pipe and stop reading at the cap.
Why is an allowlist better than a denylist?
Because you cannot list every way to hurt a system, but you can list the commands your agent needs. Anthropic’s own bash tool docs give the same advice: a blocklist misses any command it did not anticipate.
A denylist looks like “block rm, mkfs, dd, curl”. It feels productive, and it leaks. python -c "import shutil; shutil.rmtree('src')" gets past every rm-based denylist. find . -delete skips the rm check entirely. git clean -fdx wipes untracked files. The denylist grows forever and still misses things.
An allowlist flips the default. Anything not on the list is blocked, and a new binary needs a deliberate decision. You will hit “binary not allowed” errors during development. That is a feature: each one is a chance to decide whether the command is worth adding.
Be honest about its limits, though. The list above includes python, node, npm, find and git, and each of those can run arbitrary code or delete files. npm install runs package install scripts. Anthropic calls this kind of check “a tripwire for obvious mistakes, not an enforcement boundary”. The boundary is the sandbox below.
How do you sandbox the working directory?
Run every command with a cwd you control, and resolve every path the model passes against that workspace before the command runs. Reject anything that lands outside it.
# filename: path_guard.py
# description: Ensure the model cannot reach outside the agent's workspace
# with '..', symlinks, or absolute paths.
from pathlib import Path

def safe_path(workspace: Path, requested: str) -> Path:
    root = workspace.resolve()
    candidate = (root / requested).resolve()
    if not candidate.is_relative_to(root):
        raise ValueError(f'path escapes workspace: {requested}')
    return candidate
Use this in every tool that takes a path: read_file, edit_file, and any bash command whose tokens include a path. .resolve() collapses .. segments and follows symlinks, so ../../etc/passwd resolves outside the root and fails. Use is_relative_to rather than a string prefix check. A prefix check lets /work/app-evil pass for a workspace at /work/app.
A path guard only sees paths it can parse. python script.py can open any file the process can reach. For that, put the whole shell inside a container started with --network none and a read-only root, mounting only the workspace as writable. Anthropic’s bash tool docs say to run the session in a container or VM as the least-privileged user, with CPU, memory and disk limits. Claude Code’s own sandbox does the same with OS features: Seatbelt on macOS and bubblewrap on Linux. For guardrails across the rest of an agent, see the secure AI agents with guardrails lab.
How do you handle long-running commands without hanging the agent?
Use tiered timeouts keyed off the binary, and kill the whole process group when one fires. A single 30-second cap prevents hangs but also kills legitimate slow commands like pytest or npm install.
Tiers that work well:
- Fast commands (
ls,grep,cat,git status): a 10-second timeout. - Medium commands (
pytest,npm test,go build): a 120-second timeout. - Long commands (
npm install,docker build): a 600-second timeout, plus a note to the model that the command may take a while.
Pick the tier from the binary with a lookup table. The model never sets the timeout directly. It will pick a value that is either too short and kills its own test run, or too long and hangs on the first runaway.
When a timeout fires, subprocess.run kills only the direct child. A test runner’s worker processes can outlive it. Start the command with start_new_session=True so it gets its own process group, then kill the group on timeout:
# filename: run_with_group_kill.py
# description: Kill every process a command started when its timeout fires.
import os
import signal
import subprocess

def run_tokens(tokens: list[str], cwd, env, timeout: int):
    proc = subprocess.Popen(tokens, cwd=cwd, env=env, text=True,
                            stdout=subprocess.PIPE, stderr=subprocess.PIPE,
                            start_new_session=True)
    try:
        out, err = proc.communicate(timeout=timeout)
    except subprocess.TimeoutExpired:
        os.killpg(proc.pid, signal.SIGKILL)
        out, err = proc.communicate()
    return proc.returncode, out, err
When should you require human approval on a bash call?
When the binary is allowed but the specific invocation is high-impact. Common cases:
- Any
git push,git reset --hard, orgit clean -fdx. These are recoverable at best and painful either way. - Any command against a production host, detected by cwd or env.
- Any command where the model already failed once and is now trying a more aggressive variant.
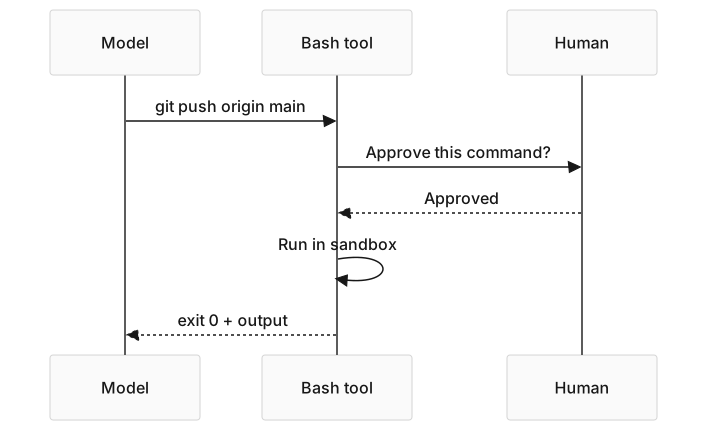
The approval flow is pause and prompt. The runtime holds the tool call, shows the command to a human, and runs it only on approval. A denial goes back to the model as the tool result, so it can choose another path. Claude Code works the same way: you can write ask rules such as Bash(git push *) that force a prompt, even in its sandbox auto-allow mode.
Should you use a bash tool or code execution?
Use a provider’s code execution tool for analysis on data you can upload. Use your own bash tool when the agent must work on your repository. They differ in where the command runs.
Anthropic’s bash_20250124 tool is a client tool. Claude returns the command, and your application runs it in a persistent bash session you own, so every layer in this guide is your job. Anthropic’s code execution tool is a server tool. It runs Python and Bash in a sandboxed container on Anthropic’s infrastructure, which cannot see your machine. For how client tool calls flow, see the tool calling guide.
What to do next
- Open your current
run_bashtool. If it usesshell=True, fix that first: split withshlexand pass a token list. - Add the allowlist. Run your agent on a real task, note every “binary not allowed”, and add only what the task needs.
- Add tiered timeouts, a process-group kill and an output cap.
- Add the path guard to every tool that takes a file argument. Check that it blocks
../../etc/passwdand a sibling directory with the same prefix. - Gate
git pushandgit reset --hardbehind human approval, then add more as you find them. - Move the whole session into a container with no network and a read-only root, as a non-root user.
- Watch these layers wired into a full coding agent in the free autonomous Claude Code agent session.
Frequently asked questions
How do you make a bash tool safe for a coding agent?
Stack independent layers: an allowlist of binaries, a tokenized call with no shell=True, a timeout, an output cap and a path guard on file arguments. Add human approval for high-impact commands. Then run the whole shell in a container or VM as a least-privileged user. The checks catch mistakes early; the isolation is what limits the damage when a check misses.
Why is an allowlist better than a denylist for bash tools?
A denylist has to name every dangerous command, and it always misses some. find . -delete and python -c both get past a denylist built around rm. An allowlist blocks everything by default, so a new command needs a deliberate decision. It is still not a security boundary, because interpreters on the list can run any code. Pair it with a sandbox.
What binaries should a coding agent’s bash tool allow by default?
Start with read-mostly tools: ls, cat, head, tail, grep, wc, pwd and echo, plus fast search tools like rg and fd. Add git, pytest, python, node and npm only when the task needs them, and know that each can run arbitrary code. Keep the list short and grow it from real tasks, not guesses.
Should I use a bash tool or a code execution tool?
Use your own bash tool when the agent must read, build and test your repository, because the commands need your files. Use a hosted code execution tool for analysis on data you can upload. Anthropic’s code execution tool runs in a sandboxed container on its own infrastructure. Its bash tool runs on your side, so you own every safety layer.
When should a bash tool require human approval?
Require approval for high-impact invocations even when the binary is allowed. Typical cases are git push, git reset --hard, anything against a production host, and a more aggressive retry after a failure. The runtime pauses the call, shows the command to a person, and runs it only on approval. A denial goes back to the model as the tool result.
Sources
- Bash tool, Anthropic, October 2026:
bash_20250124is a client tool, allowlists over blocklists, the tripwire warning, and running in a container or VM with resource limits. - Configure the sandboxed Bash tool, Anthropic Claude Code docs, October 2026: OS-enforced sandboxing with Seatbelt and bubblewrap, auto-allow mode and ask rules.
- subprocess: Security considerations, Python documentation, October 2026: why
shell=Truewith untrusted input enables shell injection. - Tool use with Claude, Anthropic, October 2026: client tools versus server tools such as code execution.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997
Or watch the recording: Build an Autonomous Claude Code Agent