Newsletter, guides
SSE vs WebSockets for streaming AI responses
When to stream LLM tokens with server-sent events or WebSockets, with FastAPI code for both, plus reconnects, cancellation, backpressure and metrics.

Your chat app streams tokens, yet users still say it feels slow. Some close the tab mid answer and the model keeps generating. A deploy drops every open stream, and nobody can resume. The protocol you picked matters less than how the stream starts, stops and recovers.
For streaming LLM responses, use server-sent events (SSE) by default. The client sends one HTTP request and the server streams tokens back over plain HTTP, with built-in reconnects through Last-Event-ID. Choose WebSockets only when the client must send messages during the stream, such as live audio, collaborative editing or many mid-stream controls. FastAPI 0.135 and later ships SSE support.
# filename: stream.py
# description: Stream LLM tokens as server-sent events with FastAPI 0.135+.
from collections.abc import AsyncIterable
from fastapi import FastAPI
from fastapi.sse import EventSourceResponse, ServerSentEvent
from llm import stream_reply

app = FastAPI()


@app.post('/chat', response_class=EventSourceResponse)
async def chat(message: str) -> AsyncIterable[ServerSentEvent]:
    i = 0
    async for token in stream_reply(message):
        i += 1
        yield ServerSentEvent(data=token, id=str(i))
    yield ServerSentEvent(raw_data='[DONE]', event='done')
Key takeaways
- SSE is one-way HTTP streaming. It fits the usual chat shape: one request in, many tokens out. It passes through proxies and load balancers that already handle HTTP.
- WebSockets are two-way and stateful. Use them when the client talks during the stream, and budget for sticky connections, heartbeats and reconnect logic you write yourself.
- A stop button does not need WebSockets. Close the SSE connection from the client, or send a separate cancel request that the stream checks.
- Give every event an
idand keep a short buffer per stream, so a reconnect withLast-Event-IDreplays what the client missed. - Stop generating when the client goes away. A stream nobody reads still costs model tokens.
- Watch time to first token, stream duration, tokens per second and disconnects. Total latency hides what users feel.
Should you use SSE or WebSockets for streaming LLM responses?
Use SSE unless the client needs to send data while tokens flow. A chat turn is a request and a long response. SSE models that directly: the browser posts the prompt and reads text/event-stream until the server ends it. Every proxy, CDN and auth middleware that understands HTTP keeps working.
WebSockets earn their cost in three cases:
- Real-time voice or audio. Audio frames go up and down at the same time.
- Shared, live state. Collaborative editors or multiplayer agents where many clients push changes.
- Chatty control. The user steers the agent many times per turn, not just once at the end.
The cost is real. A WebSocket is a long-lived stateful connection, so a load balancer must keep it on one instance, a deploy must drain it, and you write your own heartbeat, reconnect and resume logic. SSE gets reconnects from the EventSource spec.
One SSE limit to know: over HTTP/1.1, browsers allow only about 6 open connections per domain, shared across tabs. Serve the app over HTTP/2 or HTTP/3, where streams share one connection, and the limit stops mattering.
How do you stream with SSE in FastAPI?
Since FastAPI 0.135.0, import EventSourceResponse and ServerSentEvent from fastapi.sse and yield from the route, as in the snippet above. FastAPI sets Cache-Control: no-cache and X-Accel-Buffering: no, so Nginx does not buffer the stream, and sends a keep-alive comment every 15 seconds when no event is sent. That ping keeps idle proxies from closing the connection while the model thinks.
Plain data values are JSON encoded. Use raw_data for sentinels like [DONE]. SSE works with POST, not just GET, which matters because prompts are too long for a URL. The browser EventSource API only sends GET without a body, so chat clients usually read a POST stream with fetch and a stream reader, or a small library that parses text/event-stream.
Before 0.135, teams used the sse-starlette package or a StreamingResponse with media_type='text/event-stream'. Those still work. The built-in version removes the hand-written headers and pings.
How do you resume a stream after a disconnect?
Number every event and keep the last few hundred per stream in a buffer such as Redis, keyed by stream id. When the client reconnects, it sends the last id it saw in the Last-Event-ID header. The server replays everything after that id, then continues with live tokens.
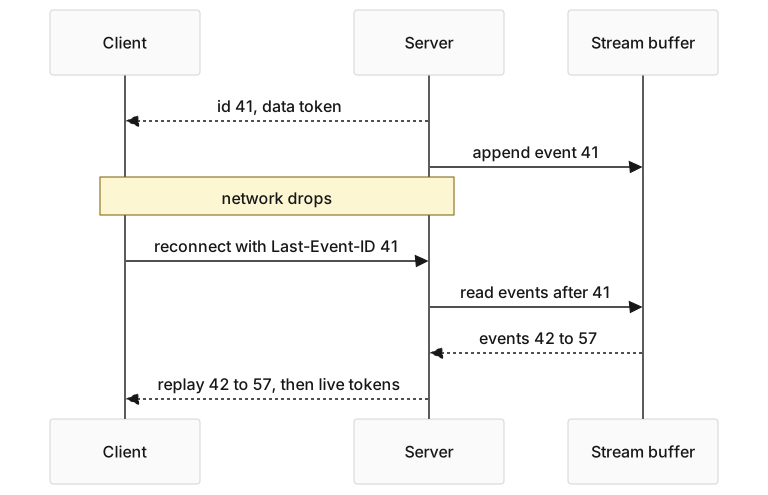
# filename: resume.py
# description: Replay buffered events after Last-Event-ID, then follow the live stream.
from typing import Annotated
from fastapi import Header
from fastapi.sse import EventSourceResponse, ServerSentEvent


@app.get('/chat/{stream_id}/events', response_class=EventSourceResponse)
async def events(
    stream_id: str,
    last_event_id: Annotated[int | None, Header()] = None,
):
    start = (last_event_id or 0) + 1
    async for i, token in buffer.read_from(stream_id, start):  # Redis stream or list
        yield ServerSentEvent(data=token, id=str(i))
The model should write into the buffer, not straight to the socket. Then the generation survives a dropped client, and any instance can serve the reconnect. Write the finished message to your database once, at the end. The connection pooling guide explains why per-token database writes hurt.
How do you cancel generation when the user hits stop?
Two ways, and you usually want both.
- The client closes the stream. The browser aborts the
fetch. The server sees the disconnect and stops the generator. Checkawait request.is_disconnected()inside long loops, and letasyncio.CancelledErrorpropagate so cleanup runs. - An explicit cancel request. For buffered streams that outlive the connection, the stop button posts to
/chat/{id}/cancel. That route sets a flag in Redis, and the generation loop checks it between tokens and closes the upstream model stream.

Close the upstream model stream when you stop. Closing it is how you tell the provider to stop generating. A forgotten background task keeps generating, and paying for, text nobody will see.
How do you stream over WebSockets in FastAPI when you need to?
Accept the socket, read client messages and send tokens on the same connection. Run generation as a task so a stop message can cancel it.
# filename: ws.py
# description: WebSocket chat with a stop message that cancels generation.
import asyncio
from fastapi import WebSocket, WebSocketDisconnect


@app.websocket('/ws/chat')
async def ws_chat(ws: WebSocket):
    await ws.accept()
    task = None

    async def generate(prompt: str):
        async for token in stream_reply(prompt):
            await ws.send_json({'type': 'token', 'data': token})
        await ws.send_json({'type': 'done'})

    try:
        while True:
            msg = await ws.receive_json()
            if msg['type'] == 'prompt':
                task = asyncio.create_task(generate(msg['text']))
            elif msg['type'] == 'stop' and task:
                task.cancel()
    except WebSocketDisconnect:
        if task:
            task.cancel()
You now own what SSE gave you for free: event ids, resume, heartbeats and a reconnect loop in the client. Configure the load balancer for long-lived upgrades and drain sockets on deploy.
How do you handle backpressure and slow clients?
Put a bounded queue between the model and each client. The model task pushes tokens into the queue. The response reads from it. If a client stops reading, for example on a weak mobile link, the queue fills, and you decide what happens: pause, batch tokens into larger chunks, or drop that client and let it resume from the buffer.
Without a bound, one tab left open on a slow link holds every token in memory. Flushing every token as its own event also costs CPU and network overhead. Batching tokens every 30 to 50 milliseconds looks just as smooth to a reader and sends far fewer frames.
Which streaming metrics should you watch?
Track these per stream, not just per request:
- Time to first token: what the user feels as speed. It includes your auth, retrieval and prompt building, not just the model.
- Tokens per second: shows slow models or slow clients.
- Stream duration and open streams per instance: your real capacity limit.
- Disconnects, resumes and cancels: a jump after a deploy means drains or reconnects are broken.
Export them as histograms. The Prometheus metrics guide covers buckets that fit long streams.
What to do next
- Default new chat endpoints to SSE with
EventSourceResponseon FastAPI 0.135 or later. - Give every event an
idand buffer recent events per stream soLast-Event-IDreconnects can replay. - Stop generation on disconnect and add a cancel route for buffered streams.
- Serve over HTTP/2 so the browser connection limit does not bite.
- Use WebSockets only for two-way cases like voice, and plan for sticky routing and drains.
- Add time to first token, tokens per second and disconnect metrics before you scale.
Frequently asked questions
Is SSE or WebSocket better for ChatGPT-style streaming?
SSE fits most chat streaming, because a turn is one request and a long one-way response. It runs over normal HTTP, works with existing proxies and auth, and reconnects with Last-Event-ID. WebSockets fit when the client sends data during the stream, such as voice audio or frequent live controls.
Does FastAPI support server-sent events natively?
Yes. FastAPI 0.135.0 added fastapi.sse with EventSourceResponse and ServerSentEvent. You yield events from the route, and FastAPI sets the no-cache and no-buffering headers and sends a keep-alive comment every 15 seconds. Older apps can keep using sse-starlette or StreamingResponse.
How do I stop an LLM stream when the user clicks stop?
Abort the request on the client, detect the disconnect on the server and stop the generator, closing the upstream model stream too. For streams that keep running into a buffer, add a cancel endpoint that sets a flag the generation loop checks between tokens.
Can SSE send a POST request with a prompt?
The SSE format works with any HTTP method, and FastAPI SSE routes can be POST. The browser’s built-in EventSource only issues GET without a body, so chat clients usually read a POST response stream with fetch or a small parsing library.
How do I resume a dropped SSE stream?
Send an id with every event and keep recent events in a buffer. On reconnect the client sends Last-Event-ID, and the server replays the events after that id before continuing live.
Sources
- Server-Sent Events (SSE), FastAPI documentation, accessed October 2026:
fastapi.sse, added in 0.135.0, the 15 second ping, headers andLast-Event-ID. - WebSockets, FastAPI documentation, accessed October 2026: accepting sockets and handling
WebSocketDisconnect. - Server-sent events, WHATWG HTML Living Standard, accessed October 2026: the event stream format,
idandLast-Event-IDreconnection. - Using server-sent events, MDN Web Docs, accessed October 2026: the per-domain connection limit over HTTP/1.1.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997