Newsletter, guides
RAG hallucination detection: Fact-check every claim
Why RAG still hallucinates with a grounded prompt, and how to catch it. Extract each claim, verify it against the retrieved context, then retry or refuse.

Your RAG pipeline retrieved the right chunks. The LLM wrote a fluent, confident answer. Then a user points out that one fact in the answer is nowhere in those chunks. The prompt said “answer only from the context”, and the model still mixed in something from its training data.
RAG fact-checking is a post-generation check that detects hallucinations by extracting each factual claim from the draft answer and verifying it against the retrieved context. Unsupported claims are flagged before the answer ships. This guide covers why grounded prompts still hallucinate, the two-stage checker with code, the rejection rule, and how to measure it.
Key takeaways
- A RAG hallucination is a claim in the answer that the retrieved context does not support, even when retrieval found the right chunks.
- A grounded prompt reduces hallucination but does not stop it, because the model can still blend context with prior knowledge or fill gaps.
- A two-stage checker first extracts discrete claims from the draft, then verifies each claim against the context, which is how Ragas computes faithfulness.
- When a claim is unsupported, the pipeline refuses, retries with stricter instructions, or removes the claim, depending on how costly a wrong answer is.
- Measure the checker on labeled questions: the share of answers with unsupported claims, and the share of refused answers.
What is a RAG hallucination?
A RAG hallucination is any claim in the generated answer that the retrieved context does not state or directly imply. The claim may even be true. What makes it a hallucination is that the answer presents it as coming from your documents when it did not.
There are two different failures to separate. A retrieval failure means the right chunk never reached the model, and tuning retriever top-k is the fix for that. A grounding failure means the right chunks arrived and the answer still added something. Fact-checking targets the second one.
Why does a grounded prompt not prevent hallucination?
Because “answer only from the context” is an instruction the model mostly follows, not a rule it cannot break. Three failure modes survive a grounded prompt:
- Blending. The model takes most of the answer from the context and a detail from prior knowledge. The detail reads as if it came from the context.
- Inference overreach. The context states A and B. The model states C, which feels implied but is not written down.
- Confident filling. The context lacks a detail, and the model fills the gap with a plausible guess instead of saying it does not know.

A second pass that checks each claim against the context catches all three, because the checker has one narrow job. Anthropic’s guide to reducing hallucinations recommends the same move: verify each claim against a supporting quote, and retract any claim without one.
How do you detect hallucinations in RAG answers?
Run a two-stage checker after generation. First, extract the discrete factual claims from the draft. Second, verify each claim against the retrieved context and return a verdict per claim.
This is the method behind two standard metrics. Ragas faithfulness divides the claims supported by the retrieved context by the total claims in the answer. FActScore splits long answers into atomic facts and scores the share a knowledge source supports.
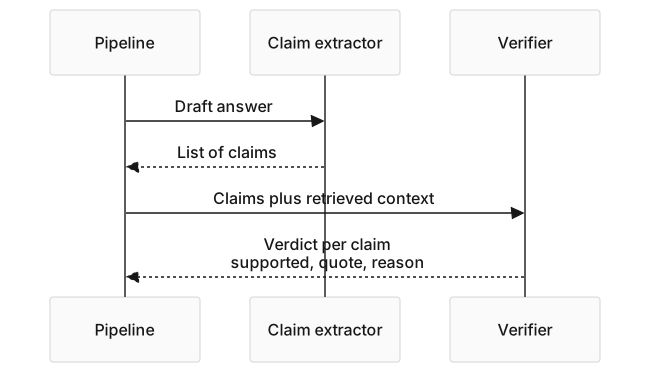
Extracting claims first matters. It forces the checker to judge one fact at a time, not the overall impression of the answer. A single-stage “is this answer grounded?” check tends to approve plausible-sounding answers.
What does the fact-checker code look like?
Two small model calls with typed outputs. The code uses Claude Haiku 5.5 with Structured Outputs through messages.parse, so each reply comes back as a validated Pydantic object instead of text you parse by hand.
# filename: app/rag/fact_check.py
# description: Two-stage fact-checker for RAG answers: extract claims, then verify each.
from anthropic import AsyncAnthropic
from pydantic import BaseModel

client = AsyncAnthropic()
MODEL = 'claude-haiku-5-5'  # a small, fast model is enough for this narrow task


class Claims(BaseModel):
    claims: list[str]


class Verdict(BaseModel):
    claim: str
    supported: bool
    quote: str  # the context sentence that supports it, or empty
    reason: str


class Verdicts(BaseModel):
    verdicts: list[Verdict]


EXTRACT_PROMPT = """Extract every discrete factual claim from the answer below.
A claim is a statement of fact that could be true or false. Ignore tone and opinions.

<answer>
{answer}
</answer>"""

VERIFY_PROMPT = """For each claim, decide if the context supports it.
A claim is supported only if the context states it or directly implies it.
Prior knowledge does not count. Quote the supporting sentence, or leave quote empty.

<context>
{context}
</context>

<claims>
{claims}
</claims>"""


async def fact_check(answer: str, context: str) -> list[Verdict]:
    extracted = await client.messages.parse(
        model=MODEL,
        max_tokens=1024,
        messages=[{'role': 'user', 'content': EXTRACT_PROMPT.format(answer=answer)}],
        output_format=Claims,
    )
    claims = extracted.parsed_output.claims
    if not claims:
        return []

    verified = await client.messages.parse(
        model=MODEL,
        max_tokens=2048,
        messages=[{'role': 'user', 'content': VERIFY_PROMPT.format(
            context=context,
            claims='\n'.join(f'- {c}' for c in claims),
        )}],
        output_format=Verdicts,
    )
    return verified.parsed_output.verdicts
The quote field makes each verdict auditable. When a reviewer doubts a “supported” verdict, the quote shows exactly which sentence the checker relied on.
What should happen when a claim is unsupported?
Pick one of three responses, based on how costly a wrong answer is compared with an “I don’t know”:
- Strict: refuse the answer and say the documents do not cover it.
- Retry: regenerate once with a stricter instruction, check again, and refuse if claims are still unsupported.
- Filter: return the answer with the unsupported claims removed and marked.
High-stakes domains such as legal, medical and financial answers should go strict. Most production assistants do well with retry, then refuse.
How do you add fact-checking to a RAG pipeline?
Add it as a step after generation. The LLM writes a draft, the checker returns verdicts, and the pipeline returns the draft, retries or refuses.

# filename: app/rag/pipeline.py
# description: RAG pipeline with post-generation fact-checking and retry-then-refuse.
from app.rag.fact_check import fact_check

REFUSAL = 'I cannot answer this from the available documents.'
STRICT = (
    'Use ONLY facts stated in the context. '
    f'If the answer is not in the context, reply exactly: "{REFUSAL}"'
)


async def rag_with_fact_check(query: str, retriever, llm) -> str:
    chunks = await retriever.search(query, k=5)
    context = '\n\n'.join(c.content for c in chunks)

    draft = await llm.generate(query, context)
    if all(v.supported for v in await fact_check(draft, context)):
        return draft

    retry = await llm.generate(query, context, extra_instructions=STRICT)
    if all(v.supported for v in await fact_check(retry, context)):
        return retry
    return REFUSAL
One retry is usually enough. If the retry still has unsupported claims, the context probably does not hold the answer, and refusing is correct. Log every refusal with the query and the retrieved chunk ids. A cluster of refusals on one topic usually points to a gap in the corpus or the retriever.
How do you measure RAG hallucination?
Label a set of real questions, run the pipeline with and without the checker, and compare two numbers. The first is the share of answers that contain at least one unsupported claim. The second is the share of answers the pipeline refused.
Both numbers matter. A checker that refuses everything scores zero hallucinations and helps nobody. Track the Ragas faithfulness score per answer in your traces so a drop shows up in a dashboard, not in a user complaint. The Langfuse and Grafana monitoring guide shows where those scores go, and the AI agent evals lab builds the labeled set from production traces.
The checker adds two model calls per answer, so it adds latency and cost. Measure both on your own traffic, and run the checker only on routes where a wrong answer is costly if the budget is tight.
What to do next
- Pull 20 to 50 queries from production where users reported a wrong fact, and label what the context did and did not support.
- Add the two-stage checker after generation, using a small model for both stages.
- Choose a rejection rule. Start with retry, then refuse, unless the domain needs strict refusal.
- Measure the unsupported-claim rate and the refusal rate before and after on the labeled queries.
- Alert when refusals rise on a topic. Rising refusals mean the retriever or the corpus is missing content.
- For multi-step questions, check facts at each hop, as in multi-hop RAG with query decomposition.
Frequently asked questions
Why do RAG answers still hallucinate with an “answer only from context” prompt?
Because the instruction lowers the risk but does not remove it. The model can blend context with what it learned in training, state an inference the context does not support, or fill a missing detail with a guess. A second pass that checks each claim against the retrieved context catches what the prompt let through.
How do you reduce hallucinations in RAG?
Fix retrieval first, so the right chunks reach the model. Then tell the model it may say it does not know, and ask it to answer from quoted context. Finally, add a post-generation fact-check that verifies each claim and retries or refuses when a claim is unsupported. Measure each step on labeled questions to see what it changes.
What is the two-stage fact-checking pattern?
The first stage extracts discrete factual claims from the draft answer. The second stage checks each claim against the retrieved context and returns a verdict, ideally with the supporting quote. Splitting the work makes the checker judge one fact at a time. A single question such as “is this answer grounded?” tends to approve plausible answers.
How do you evaluate RAG hallucination detection?
Label real questions with what the context does and does not support. Run the pipeline with and without the checker, then compare the share of answers with unsupported claims and the share of refused answers. Ragas faithfulness gives a per-answer score: supported claims divided by total claims. Track it over time in your traces.
Should the fact-checker use the same model as the generator?
It does not need to. Claim extraction and per-claim verification are narrow tasks, so a small, fast model such as Claude Haiku usually handles them. Use a larger model for the verifier only if your labeled set shows the small one missing unsupported claims. Keep the checker’s prompt separate from the generator’s so they do not share the same blind spots.
Sources
- Faithfulness, Ragas documentation: faithfulness extracts claims from the response and divides the supported claims by the total.
- FActScore: Fine-grained Atomic Evaluation of Factual Precision in Long Form Text Generation, Min et al., EMNLP 2023: score answers by the share of atomic facts a knowledge source supports.
- Reduce hallucinations, Anthropic Claude docs: allow “I don’t know”, ground in quotes, and retract claims without a supporting quote.
- Structured outputs, Anthropic Claude docs, October 2026:
messages.parsewith a Pydantic model, and Claude Haiku 5.5 support.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild AI Agent Evals from Production TracesA test set built from real agent runs, scored by code checks and an LLM judge, that fails the build when the agent gets worse.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997