Newsletter, guides
LangGraph with FastAPI: A production chatbot API
Wire LangGraph into FastAPI with token streaming over SSE, a Postgres checkpointer, per-user thread IDs and human in the loop with interrupt.
You built a chatbot with LangGraph in a notebook. State flows through the graph, an in-memory checkpointer keeps the history, and it works. Then you wrap it in a FastAPI /chat route and deploy. Users wait with no visible progress, a restart wipes every conversation, and you are not sure two users cannot read each other’s threads.
A LangGraph FastAPI chatbot API is a service pattern that serves a graph over HTTP by keying each conversation by thread_id and streaming tokens as SSE. This guide is the production version of that wiring. It covers streaming, a Postgres checkpointer, composite thread IDs, safe error events and human in the loop with interrupt.
Key takeaways
- Compile the LangGraph graph once per worker in the FastAPI
lifespanblock, not once per request. - Every run with a checkpointer needs
config={'configurable': {'thread_id': ...}}. LangGraph raises aValueErrorwhen it is missing. - Build the thread ID from tenant, user and session, so conversations never collide across users.
- Use
AsyncPostgresSaverfromlanggraph-checkpoint-postgresin production.InMemorySaverloses every thread when the process restarts. - Stream tokens with
graph.astream(..., stream_mode='messages')and FastAPI’sEventSourceResponse. The defaultupdatesmode only emits whole node outputs. - Pause for human approval with
interrupt(), then resume the same thread withCommand(resume=...)from a second endpoint.
Why does the naive LangGraph and FastAPI wiring fail?
Because the notebook setup hides three production problems. Each one has a direct fix.
- No durable state.
InMemorySaverkeeps checkpoints in process memory. A deploy or a crash loses every conversation, and a second worker cannot see the first worker’s threads. - No token streaming.
graph.ainvokereturns only after the whole run.graph.astreamwith the defaultupdatesmode emits one event per finished node, so the user still waits for the full reply. - Weak thread keys. LangGraph does not invent a thread for you. With a checkpointer, a run without
thread_idraises an error. A thread ID built from a client value alone, such assession_id, lets one user load another user’s thread.
The fix is a Postgres checkpointer, stream_mode='messages' and a thread ID built on the server from the authenticated user.
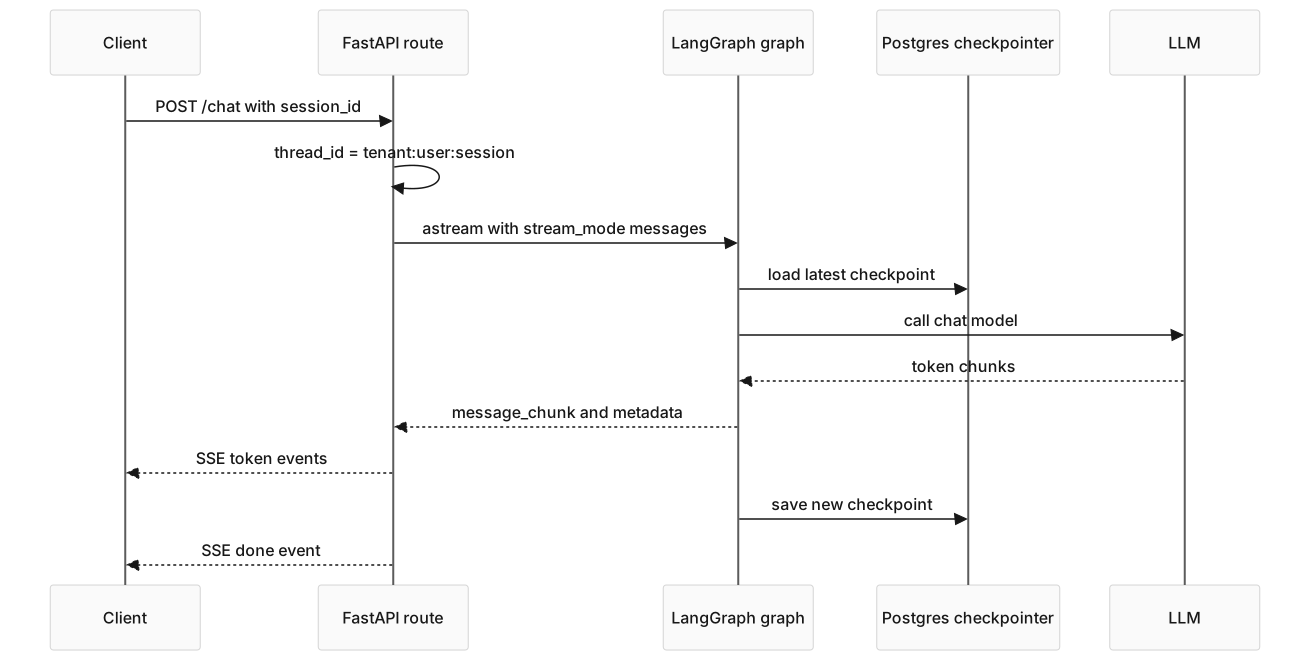
How do you use LangGraph with FastAPI?
Compile the graph once at startup, build the thread ID from the authenticated request, and stream tokens. The route below does all three.
# filename: app/main.py
# description: FastAPI + LangGraph production chatbot API.
# Compile graph at startup, persist to Postgres, stream tokens via SSE.
import logging
from collections.abc import AsyncIterable
from contextlib import asynccontextmanager

from fastapi import Depends, FastAPI
from fastapi.sse import EventSourceResponse, ServerSentEvent
from langgraph.checkpoint.postgres.aio import AsyncPostgresSaver
from pydantic import BaseModel

from app.auth import AuthContext, get_auth
from app.config import get_settings
from app.domain.graph import build_graph

logger = logging.getLogger(__name__)


@asynccontextmanager
async def lifespan(app: FastAPI):
    db_url = get_settings().database_url
    async with AsyncPostgresSaver.from_conn_string(db_url) as checkpointer:
        await checkpointer.setup()  # creates the checkpoint tables once
        app.state.graph = build_graph(checkpointer=checkpointer)
        yield


app = FastAPI(lifespan=lifespan)


class ChatRequest(BaseModel):
    session_id: str
    message: str


def thread_config(auth: AuthContext, session_id: str) -> dict:
    thread_id = f'{auth.tenant_id}:{auth.user_id}:{session_id}'
    return {'configurable': {'thread_id': thread_id}}


@app.post('/chat', response_class=EventSourceResponse)
async def chat(
    body: ChatRequest,
    auth: AuthContext = Depends(get_auth),
) -> AsyncIterable[ServerSentEvent]:
    config = thread_config(auth, body.session_id)
    inputs = {'messages': [{'role': 'user', 'content': body.message}]}
    try:
        async for chunk, metadata in app.state.graph.astream(
            inputs, config, stream_mode='messages'
        ):
            if metadata['langgraph_node'] == 'llm' and isinstance(chunk.content, str) and chunk.content:
                yield ServerSentEvent(data=chunk.content, event='token')
    except Exception:
        logger.exception('graph run failed', extra={'thread_id': config['configurable']['thread_id']})
        yield ServerSentEvent(data='Something went wrong. Please try again.', event='error')
    yield ServerSentEvent(raw_data='[DONE]', event='done')
Five decisions in this file matter:
- The graph is compiled once per worker in
lifespan, so requests share it. - The checkpointer is
AsyncPostgresSaver, so threads survive restarts and every worker reads the same store. - The thread ID is built on the server from the authenticated tenant and user, plus the client’s session.
stream_mode='messages'yields(message_chunk, metadata)pairs for each LLM token. Thelanggraph_nodefilter keeps only tokens from the reply node.EventSourceResponse(FastAPI 0.135 and later) setsCache-Control: no-cacheandX-Accel-Buffering: noand sends keep-alive pings.
from_conn_string opens one connection per worker. Under heavier load, pass a psycopg_pool.AsyncConnectionPool to AsyncPostgresSaver(pool) instead. Its connections must use autocommit=True and row_factory=dict_row, as the checkpointer README requires.
For workers, timeouts and the rest of the server setup, see what Uvicorn is and how to run FastAPI agents.
How does the graph keep the conversation history?
Through a state reducer and the checkpointer together. MessagesState declares its messages key with the add_messages reducer. So a node returns only the new message, and LangGraph appends it to the history it loaded from the checkpoint.
# filename: app/domain/graph.py
# description: LangGraph state graph with a passed-in checkpointer.
from langgraph.graph import END, START, MessagesState, StateGraph

from app.infra.llm import chat_model  # a LangChain chat model


async def llm_node(state: MessagesState) -> dict:
    reply = await chat_model.ainvoke(state['messages'])
    return {'messages': [reply]}


def build_graph(checkpointer):
    builder = StateGraph(MessagesState)
    builder.add_node('llm', llm_node)
    builder.add_edge(START, 'llm')
    builder.add_edge('llm', END)
    return builder.compile(checkpointer=checkpointer)
Do not declare state as a plain messages: list[dict]. A key without a reducer is overwritten by each input. With a checkpointer, the new user message would replace the stored history instead of joining it.
Token streaming in messages mode works when the node calls a LangChain chat model. On Python below 3.11, pass the node’s config into ainvoke so the tokens still reach the stream.
Why build the thread ID from tenant, user and session?
Because LangGraph treats thread_id as the only key for a conversation. If you use the session ID alone, a client can send another user’s session ID and read that thread. If you use the user ID alone, every chat from that user lands in one thread. The composite tenant:user:session isolates users and still lets one user keep many conversations, one per session.
The first two parts must come from your auth layer, never from the request body. For more thread layouts, see LangGraph persistence and thread models.
How does the Postgres checkpointer survive restarts?
It saves a checkpoint of the graph state to Postgres after each step. The next request with the same thread_id loads the latest checkpoint and continues from there. The state is not in the process, so a deploy or a worker restart does not lose it.
Call checkpointer.setup() once to create the tables. Running it at startup, as above, is safe for a small service. In a larger system, run it as a migration step before the app starts.
How do you send errors without breaking the SSE stream?
Catch the exception inside the generator and yield an error event. If the exception escapes, the connection drops mid-stream and the client sees a broken response with no reason.
Keep two rules. First, send the user a generic message and log the details on the server, with the thread ID. Stack traces, provider names and raw errors never belong in a customer-facing event. Second, yield the final [DONE] event after the try block, not inside finally. When the client disconnects, Python closes the generator, and a yield in finally then raises a RuntimeError. For retrying the LLM call before it fails the stream, see retry patterns for LLM API errors.
How do you add human in the loop with interrupt in FastAPI?
Call interrupt() inside a node, end the stream with an approval event, and resume the same thread from a second endpoint with Command(resume=...). The checkpointer stores the paused state between the two requests.
# filename: app/routes/approval.py
# description: Human in the loop. A node pauses with interrupt(), the client
# sees an approval event, and /chat/resume continues the same thread.
from langgraph.types import Command, interrupt


def approve_refund(state: RefundState) -> dict:
    decision = interrupt({'question': 'Approve this refund?', 'amount': state['amount']})
    return {'approved': decision == 'yes'}


@app.post('/chat/resume', response_class=EventSourceResponse)
async def resume(
    body: ResumeRequest,
    auth: AuthContext = Depends(get_auth),
) -> AsyncIterable[ServerSentEvent]:
    config = thread_config(auth, body.session_id)
    async for chunk, metadata in app.state.graph.astream(
        Command(resume=body.decision), config, stream_mode='messages'
    ):
        if isinstance(chunk.content, str) and chunk.content:
            yield ServerSentEvent(data=chunk.content, event='token')
    yield ServerSentEvent(raw_data='[DONE]', event='done')
In the /chat route, check for a pause after the stream ends. Call await app.state.graph.aget_state(config) and read snapshot.interrupts. If it is not empty, yield an approval event with each interrupt’s value before [DONE].
On resume, LangGraph runs the paused node again from its first line. Code before interrupt() runs twice, so keep it free of side effects such as charges or emails.

What to do next
- Replace
InMemorySaverwithAsyncPostgresSaverand runsetup()once. - Move graph compilation into the FastAPI
lifespanblock. - Build the thread ID from the authenticated tenant and user plus the session. Test that one user cannot load another user’s thread.
- Switch the state to
MessagesState, or add theadd_messagesreducer to yourmessageskey. - Stream with
stream_mode='messages'throughEventSourceResponse. - Make the LLM client raise on purpose and confirm the client gets a generic error event, then
[DONE]. - If an action needs approval, add an
interrupt()node and a resume endpoint.
Frequently asked questions
How do you deploy LangGraph with FastAPI?
Run the FastAPI app with Uvicorn and compile the graph in the lifespan block of each worker. Point the graph at a shared Postgres checkpointer so every worker and every restart sees the same threads. Put auth in front of the routes and build the thread ID from the authenticated user. Disable --reload and keep the graph code free of blocking calls.
How do you stream LangGraph output through FastAPI?
Call graph.astream with stream_mode='messages' inside an async generator. Each item is a (message_chunk, metadata) pair, and metadata['langgraph_node'] tells you which node produced it. Yield each chunk as a ServerSentEvent and return the generator with response_class=EventSourceResponse. FastAPI then sets the no-cache and no-buffering headers for you.
How do you isolate conversations between users in LangGraph?
Build a composite thread_id such as tenant_id:user_id:session_id, and take the tenant and user from your auth layer. LangGraph keys every checkpoint by thread ID, so different IDs never share state. The session part lets one user keep several parallel conversations. Never accept a full thread ID from the client.
Why is AsyncPostgresSaver better than InMemorySaver?
InMemorySaver keeps checkpoints in process memory. A restart wipes every conversation, and each worker sees only its own threads. AsyncPostgresSaver writes each checkpoint to Postgres, so threads survive deploys and all workers share one store. The LangGraph docs suggest the in-memory saver for experiments and a durable checkpointer for production.
How do you add human in the loop to a LangGraph FastAPI app?
Call interrupt() in the node that needs approval. The run pauses and the checkpointer saves its state. Your /chat route sees the pause through aget_state(config).interrupts and sends an approval event. A second endpoint resumes the same thread with Command(resume=decision). The paused node then runs again from its start.
Sources
- LangGraph persistence, LangChain docs, 2026: checkpointers,
thread_idinconfigurable, and in-memory versus durable savers. - LangGraph streaming, LangChain docs, 2026: stream modes and the
(message_chunk, metadata)shape ofmessagesmode. - LangGraph interrupts, LangChain docs, 2026:
interrupt(),Command(resume=...)and nodes that rerun on resume. - langgraph-checkpoint-postgres README, LangChain on GitHub, 2026:
AsyncPostgresSaver,setup(), and theautocommitanddict_rowrequirements. - Server-sent events, FastAPI docs, 2026:
EventSourceResponseover POST and the headers it sets.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997