Newsletter, guides
What is Uvicorn? Run FastAPI agents in production
What Uvicorn is, why FastAPI needs it, and the production command, workers, lifespan and SSE streaming setup that keeps AI agents up under real traffic.
Your agent works on your laptop. You wrap it in a FastAPI route, run uvicorn main:app --reload, and the response streams back. Then you put it behind a real URL. A second user hits the endpoint while the first is mid tool call, and the whole server stalls. A deploy drops every open conversation.
Uvicorn is an ASGI web server for Python that runs FastAPI apps by running the asyncio event loop and handing each request to your route. FastAPI defines routes and validation. Uvicorn is the process that serves them. Most production failures in an agent service come from how Uvicorn runs your code, not from the agent itself. This guide covers what Uvicorn is, the production command, workers, lifespan and streaming.
Key takeaways
- Uvicorn is the ASGI server that runs a FastAPI app. FastAPI does not listen on a port by itself.
--reloadis for development only. In production runfastapi runoruvicornwith--workers, and never with--reload.- Each Uvicorn worker is a separate process with its own event loop. One blocking call inside an
async defroute freezes every request on that worker. - Create LLM and database clients in a FastAPI
lifespanblock, so each worker opens and closes its own clients cleanly. - FastAPI 0.135 and later ships
EventSourceResponsefor server-sent events, with keep-alive pings and theX-Accel-Buffering: noheader set for you. - Gunicorn is optional now. Uvicorn’s own process manager restarts dead workers, and
uvicorn.workersis deprecated in favor of theuvicorn-workerpackage.
What is Uvicorn and why does FastAPI need it?
Uvicorn is the server, and FastAPI is the application. FastAPI is a framework for routing, validation and docs. It does not open a socket, manage processes or parse HTTP. Uvicorn does all of that and calls your app through the ASGI interface.
ASGI is the async successor to WSGI. WSGI, used by Flask and classic Django, maps one request to one blocking call and one response. ASGI gives you an event loop, long-lived connections, server-sent events and WebSockets. An agent needs all of those, because one chat turn can hold a connection open for many seconds while it streams.

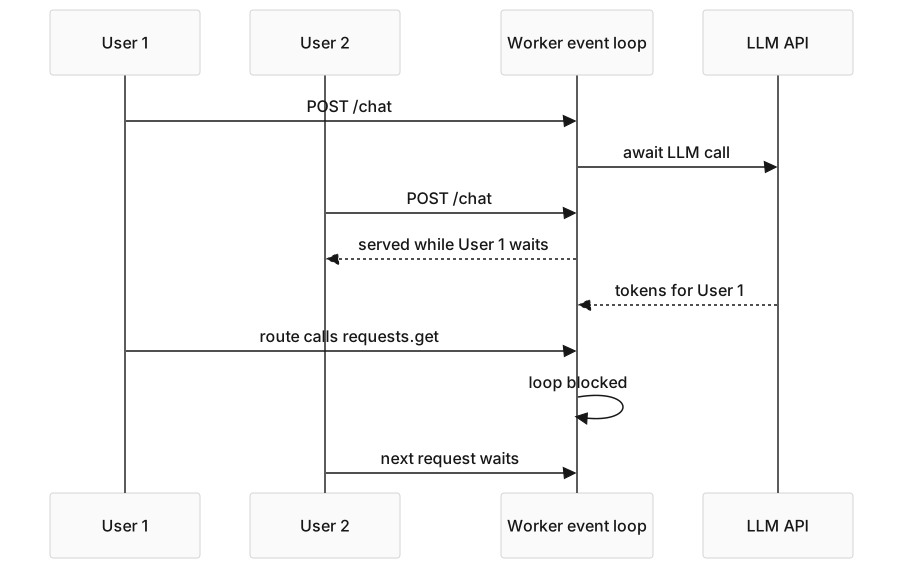
Remember one rule: Uvicorn owns the event loop, and your agent code runs on that loop. Anything that blocks the loop blocks every user on that worker.
Why do agent workloads break the default setup?
Because an agent request is long, streaming and mostly waiting on the network. A CRUD request reads a row and returns in milliseconds. One /chat call to an agent might do all of this:
- Call the LLM and wait seconds for the first tokens.
- Run a tool, such as a SQL query or an HTTP call.
- Call the LLM again with the tool output.
- Stream tokens back to the user the whole time.
- Save state so a refresh does not lose the conversation.
With one worker and a few users, the loop handles this well, as long as every step awaits. If one step calls a sync function, the loop stops, and every other user on that worker waits. Your laptop hides this because you are the only user.
Why use FastAPI instead of Flask for AI agents?
Because FastAPI is async first and Flask is sync first. Flask serves each request on a thread. Streaming LLM tokens means fighting the framework and picking a special server. FastAPI gives you async def routes, server-sent events and Pydantic models out of the box.
The Pydantic part matters for agents. FastAPI validates request bodies with Pydantic models. Most LLM tool calling libraries describe tool inputs with the same JSON Schema. You write the schema once and use it at the HTTP edge and at the tool edge. For how tool schemas reach the model, see tool calling for LLMs.
What is the Uvicorn command for production?
Use fastapi run, or call uvicorn directly with workers and no reload. Both start Uvicorn. fastapi run listens on 0.0.0.0 with reload off. fastapi dev listens on 127.0.0.1 with reload on, which is for your laptop only.
# filename: run.sh
# description: Production Uvicorn command for an agent service.
# Run inside the container as a non-root user.
uvicorn app.main:app \
  --host 0.0.0.0 \
  --port 8000 \
  --workers 4 \
  --timeout-keep-alive 75 \
  --timeout-graceful-shutdown 30 \
  --forwarded-allow-ips '10.0.0.0/8'

# The same app through the FastAPI CLI:
# fastapi run app/main.py --workers 4
Flag by flag:
--workers 4: starts that many processes, each with its own event loop. The default is$WEB_CONCURRENCY, or 1. As an example starting point, try twice the CPU count, then load test. More workers also means more parallel calls to your LLM provider, so you reach its rate limit sooner.--timeout-keep-alive 75: how long an idle keep-alive connection stays open between requests. The default is 5 seconds. Set it above your load balancer’s idle timeout, so the server does not close a connection the balancer still reuses.--timeout-graceful-shutdown 30: on a deploy, Uvicorn waits up to this many seconds for open requests before it terminates them. Without it, a redeploy can cut off streaming answers.--forwarded-allow-ips: proxy headers are on by default, but Uvicorn only trusts them from127.0.0.1and::1. List your proxy’s address or network so logs show real client IPs. Use'*'only when nothing but the proxy can reach the port.
Notice what is missing: --reload. It watches files and cannot be used with --workers. If you see --reload in a production Dockerfile, that is your bug.
If your app is built by a function, add --factory and point Uvicorn at the function, such as uvicorn app.main:create_app --factory. Uvicorn calls it to get the ASGI app.
Should you use Uvicorn or Gunicorn for AI workloads?
Use Uvicorn directly for most new services. Uvicorn’s --workers mode now runs a process manager that restarts workers that die and kills stuck ones. It also has --limit-max-requests, which recycles a worker after a set number of requests. That covers the main reasons people reached for Gunicorn.
If your platform already runs Gunicorn, keep it. Note that the uvicorn.workers module is deprecated. Install the uvicorn-worker package and run gunicorn app.main:app -w 4 -k uvicorn_worker.UvicornWorker.
On Kubernetes, the FastAPI docs suggest the opposite of workers: one Uvicorn process per container. The cluster then handles replication and restarts.
How do you stream LLM responses with FastAPI?
Return an EventSourceResponse and yield events from an async generator. FastAPI added it in version 0.135. It formats each event, sends a keep-alive ping every 15 seconds when the stream is quiet, and sets Cache-Control: no-cache and X-Accel-Buffering: no for you.
# filename: app/routes/chat.py
# description: Streaming endpoint for an agent. Yields one SSE event
# per token as the agent produces them.
from collections.abc import AsyncIterable

from fastapi import APIRouter
from fastapi.sse import EventSourceResponse, ServerSentEvent
from pydantic import BaseModel

from app.agent import run_agent  # your agent's async generator

router = APIRouter()


class ChatRequest(BaseModel):
    message: str


@router.post('/chat', response_class=EventSourceResponse)
async def chat(body: ChatRequest) -> AsyncIterable[ServerSentEvent]:
    async for token in run_agent(body.message):
        yield ServerSentEvent(data=token, event='token')
    yield ServerSentEvent(raw_data='[DONE]', event='done')
On an older FastAPI, use StreamingResponse with media_type='text/event-stream'. Then write the data: ...\n\n lines and both headers yourself.
Two things still break streaming. First, a proxy or CDN in front can buffer the response, so the stream arrives as one block. Test through the real URL with curl -N. Second, every call inside run_agent must await. One requests.get(...) instead of await client.get(...) with httpx stops the stream for every user on that worker.
For a full chatbot route that streams LangGraph output this way, see the FastAPI and LangGraph chatbot API guide.
How do you find code that blocks the event loop?
Search for sync I/O inside async def routes and the code they call. The usual cases are requests, time.sleep, sync database drivers and sync LLM clients. Replace them with httpx, asyncio.sleep, an async driver such as asyncpg, and the async client of your LLM SDK.
When there is no async version, move the call off the loop. Use await run_in_threadpool(fn, *args) from starlette.concurrency, or declare the route with plain def. FastAPI runs plain def routes in a thread pool, so they do not block the loop.
Why should clients live in the FastAPI lifespan?
Because lifespan runs once per worker, before that worker takes requests, and again at shutdown. That is the right place to open and close long-lived clients. A client created at import time has no shutdown hook. Its connections are never closed cleanly on a deploy.
# filename: app/main.py
# description: Lifespan-managed clients so each Uvicorn worker opens its
# own pool at startup and closes it at shutdown.
from contextlib import asynccontextmanager

from fastapi import FastAPI
from openai import AsyncOpenAI

from app.db import create_pg_pool


@asynccontextmanager
async def lifespan(app: FastAPI):
    app.state.llm = AsyncOpenAI()
    app.state.db = await create_pg_pool()
    yield
    await app.state.db.close()
    await app.state.llm.close()


app = FastAPI(lifespan=lifespan)
Each Uvicorn worker is its own process and imports your app itself. With lifespan, every worker builds its clients inside its own running event loop and closes them on shutdown. This also stays safe under Gunicorn with --preload, where workers are forked from a parent that already imported the app. The older @app.on_event('startup') handlers are deprecated, and they do not run when you pass lifespan.
The production AI chatbot system design guide applies the same pattern to vector stores, Redis and the LangGraph runtime.
What to do next
- Open your
Dockerfile. Remove--reloadand usefastapi runor theuvicorncommand above. - Set
--workers,--timeout-graceful-shutdownand--forwarded-allow-ipsfor your platform. On Kubernetes, run one process per container instead. - Search the code for
requests.,time.sleepand sync drivers insideasync def. Swap them for async versions or move them to a thread pool. - Move every long-lived client into a
lifespanblock and read it fromapp.state. - Switch streaming routes to
EventSourceResponseand test them through the real URL withcurl -N. - Load test with several concurrent fake users sending agent prompts, and watch whether the second user waits on the first.
Frequently asked questions
What is Uvicorn used for?
Uvicorn is used to run async Python web apps that follow the ASGI standard, such as FastAPI and Starlette. It listens on a port, parses HTTP and WebSocket traffic, runs the event loop, and passes each request to your app. In production it also manages worker processes. Without an ASGI server like Uvicorn or Hypercorn, a FastAPI app cannot serve traffic.
What does Uvicorn do for FastAPI?
Uvicorn turns a FastAPI app into a running server. FastAPI builds the ASGI app: routes, validation and OpenAPI docs. Uvicorn opens the socket, accepts connections, runs the asyncio loop and calls the app for each request. The fastapi run and fastapi dev commands both start Uvicorn for you, with production or development defaults.
Which is better, ASGI or WSGI?
ASGI is the better fit for AI agents and any app that streams or holds connections open. WSGI handles one blocking request per worker thread and has no native support for WebSockets or long streams. ASGI runs many requests on one event loop while they wait on the network. WSGI is still fine for short, sync CRUD apps built on Flask or classic Django.
Should I use Uvicorn or Gunicorn for an AI agent?
Use Uvicorn with --workers for most new services. Its process manager restarts dead workers, and --limit-max-requests recycles them. Choose Gunicorn only if your platform already standardizes on it. In that case install the uvicorn-worker package and pass -k uvicorn_worker.UvicornWorker, because the old uvicorn.workers module is deprecated.
How many Uvicorn workers should I run for an agent service?
Start near twice your CPU count and load test from there. Agent requests mostly wait on the network, so one worker can hold many open requests at once. Each extra worker also adds parallel calls to your LLM provider, so throughput can drop when you hit its rate limit. On Kubernetes, run one worker per container and scale pods.
Why does my FastAPI agent stop responding under load?
The most common cause is a sync call inside an async def route. A requests.get, a sync database query or a time.sleep blocks the event loop and freezes every user on that worker. Replace it with an async library such as httpx or asyncpg. If none exists, run the call with run_in_threadpool or make the route a plain def.
Sources
- Uvicorn settings, Uvicorn docs, 2026: defaults for
--workers,--timeout-keep-alive,--forwarded-allow-ipsand the--factoryand--limit-max-requestsoptions. - Uvicorn deployment, Uvicorn docs, 2026: the process manager that restarts workers and the deprecation of
uvicorn.workersin favor ofuvicorn-worker. - Server workers: Uvicorn with workers, FastAPI docs, 2026:
fastapi run --workersand one process per container on Kubernetes. - Server-sent events, FastAPI docs, 2026:
EventSourceResponsesince 0.135, keep-alive pings and the headers it sets. - Lifespan events, FastAPI docs, 2026: startup and shutdown code in
lifespan, and the deprecated event handlers.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997