Newsletter, guides
AI chatbot system design: A production architecture
AI chatbot system design for production, end to end. Streaming over SSE, memory, tools, rate limits, circuit breakers, versioning and tracing, with code.

“Build a chatbot” sounds like a junior interview question. Then it ships. Users stare at a spinner for ten seconds. The bot forgets their name. One script drains the API budget overnight, and a provider outage takes the product down. A Python script that calls an LLM API is a demo, not a product.
AI chatbot system design is the architecture work that turns an LLM call into a service, by splitting it into layers for streaming, memory, tools, limits and observability. This guide walks the end-to-end design: what each layer does, which tools to pick, and the code for the parts that break first in production.
Key takeaways
- A production chatbot is an async service split into layers: client, edge, chat service, AI orchestration and storage. One slow layer does not block the rest.
- Stream tokens to the browser with server-sent events (SSE). Users see the first words fast, and SSE runs over plain HTTP.
- Keep memory per conversation with a thread ID, send recent messages, and summarize older ones so the prompt stays inside a token budget.
- Rate-limit per user by requests and by tokens in Redis, and wrap each LLM provider in a circuit breaker with a fallback.
- Record the model and prompt version on every assistant message, and trace every request, so you can explain a bad answer and roll back a bad release.
What does a production AI chatbot architecture look like?
It is an event-driven, asynchronous service split into five layers. Each layer has one job, so a slow or failing part degrades the experience instead of stopping it.

- Client: the chat window. It shows the user’s message at once, renders tokens as they arrive, and shows errors.
- Edge: the load balancer or API gateway. It routes requests, checks authentication and blocks abuse.
- Chat service: the coordinator. It loads conversation state, applies rate limits and streams the reply.
- AI layer: the orchestrator. It calls the LLM, decides when to use tools or retrieval (RAG), and runs them.
- Persistence: Postgres for chat history, Redis for rate limits, caches and short-lived state.
System design and product architecture overlap but answer different questions. Product architecture decides which features exist and how users move through them. System design decides how those features stay fast, correct and available under load.
Which tech stack should you use for an AI chatbot?
A common, well-supported stack is React with the Vercel AI SDK on the client, FastAPI on the server, and Postgres plus Redis for storage. Pick tools your team can run, but keep the async and streaming properties.
Frontend: React and the AI SDK
Parsing a token stream by hand means handling partial events, message state, errors and stop buttons. The AI SDK’s useChat hook does this for you. Since AI SDK 5 the hook lives in @ai-sdk/react, messages carry parts, and you manage the input field yourself.
// filename: app/chat.tsx
// description: Chat UI with the AI SDK useChat hook (AI SDK 5 and later).
import { useChat } from '@ai-sdk/react';
import { useState } from 'react';

export function Chat() {
  const [input, setInput] = useState('');
  const { messages, sendMessage, status, stop, error } = useChat(); // posts to /api/chat

  return (
    <form
      onSubmit={(e) => {
        e.preventDefault();
        sendMessage({ text: input });
        setInput('');
      }}
    >
      {messages.map((m) => (
        <div key={m.id}>
          {m.role}: {m.parts.map((p, i) => (p.type === 'text' ? <span key={i}>{p.text}</span> : null))}
        </div>
      ))}
      <input value={input} onChange={(e) => setInput(e.target.value)} />
      <button disabled={status !== 'ready'}>Send</button>
      {status === 'streaming' && <button type="button" onClick={stop}>Stop</button>}
      {error && <p>Something went wrong. Try again.</p>}
    </form>
  );
}
useChat expects the AI SDK’s UI message stream protocol by default. A Python backend must emit that format, or you pass a TextStreamChatTransport for plain text streams.
Backend: FastAPI with async everywhere
Python is where most AI libraries live, and FastAPI gives you async handlers, Pydantic validation and OpenAPI docs. The rule that matters is async I/O all the way down. A blocking LLM call inside a sync handler ties up a worker for the whole generation.
# filename: app/blocking.py
# description: The difference between a blocking and a non-blocking LLM call.
from openai import AsyncOpenAI, OpenAI

# BAD: the sync client blocks this worker until the full answer arrives
@app.post("/chat-sync")
def chat_sync(req: ChatRequest):
    return OpenAI().chat.completions.create(model=settings.chat_model, messages=req.messages)

# GOOD: the async client frees the event loop while it waits
client = AsyncOpenAI()

@app.post("/chat")
async def chat(req: ChatRequest):
    return await client.chat.completions.create(model=settings.chat_model, messages=req.messages)
For the full service around this endpoint, see the FastAPI and LangGraph chatbot API.
Storage: Postgres and Redis, two jobs
Postgres holds the durable record: sessions, messages and token counts. Redis holds fast, short-lived counters for rate limits and caches. Counting requests in the last hour is a cheap INCR in Redis and a slow query in Postgres.
-- filename: db/schema.sql
-- description: Chat sessions and messages, with the version fields used for rollbacks.
CREATE TABLE chat_sessions (
    id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    user_id UUID NOT NULL,
    thread_id VARCHAR(255) NOT NULL UNIQUE,
    created_at TIMESTAMPTZ DEFAULT NOW(),
    metadata JSONB
);

CREATE TABLE chat_messages (
    id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    session_id UUID REFERENCES chat_sessions(id),
    role VARCHAR(20) NOT NULL,          -- 'user', 'assistant' or 'tool'
    content TEXT NOT NULL,
    tokens_used INTEGER,
    model VARCHAR(100),                 -- exact model ID that wrote this message
    prompt_version VARCHAR(50),         -- system prompt version in git
    created_at TIMESTAMPTZ DEFAULT NOW()
);

CREATE INDEX idx_session_messages ON chat_messages(session_id, created_at);
Should you use SSE or WebSockets for chatbot streaming?
Use SSE for most chatbots. The server pushes tokens one way over plain HTTP, which is the shape of a chat reply, and the OpenAI and Anthropic APIs stream the same way.
| SSE | WebSockets | |
|---|---|---|
| Direction | Server to client | Both ways |
| Transport | Plain HTTP response | Upgraded connection |
| Reconnection | EventSource reconnects by default |
You build it |
| Fits | Chat replies, notifications | Voice, games, shared editing |
Two limits to know. The browser EventSource API only sends GET, so chat clients usually POST with fetch and read the stream body, which the AI SDK does for you. Over HTTP/1.1, browsers allow only six open connections per domain, so serve SSE over HTTP/2. Choose WebSockets when the client must send events mid-stream, as in voice.
Why is my AI chatbot slow in production?
Usually because nothing reaches the user until the whole answer exists. Fix it by streaming tokens as they arrive and by keeping slow work, such as database writes, off the path to the first token.
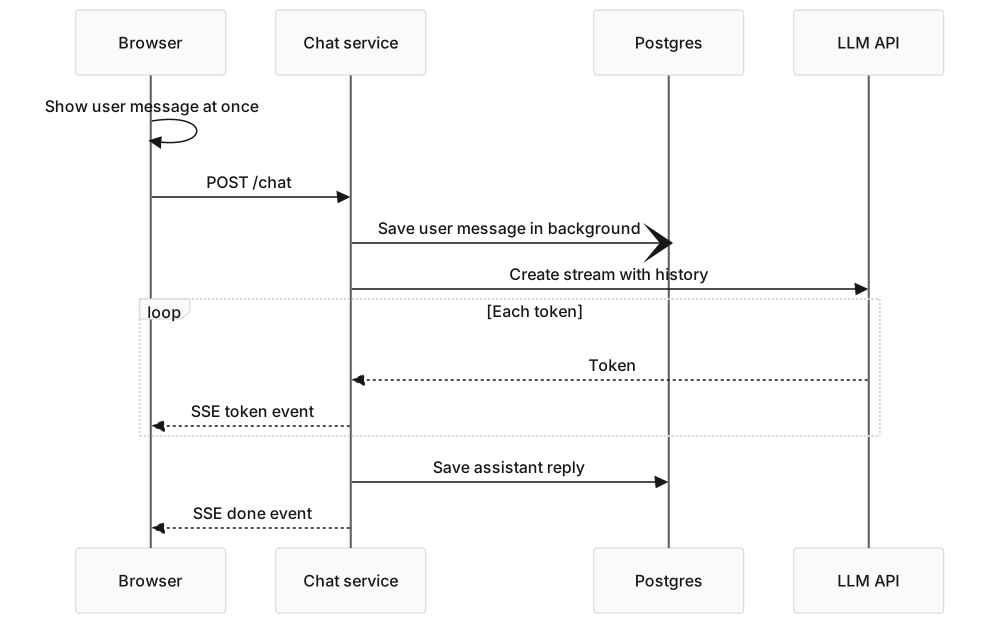
The browser shows the user’s message at once (an optimistic update). The server starts the LLM call as soon as it has the context. It saves the user’s message in the background and saves the reply after the stream ends. FastAPI 0.135 and later ship SSE support in fastapi.sse. On older versions, the sse-starlette package does the same job.
# filename: app/stream.py
# description: Stream LLM tokens over SSE with FastAPI and the async OpenAI client.
import asyncio
from collections.abc import AsyncIterable

from fastapi import FastAPI
from fastapi.sse import EventSourceResponse, ServerSentEvent
from openai import AsyncOpenAI

app = FastAPI()
client = AsyncOpenAI()

@app.post("/chat", response_class=EventSourceResponse)
async def chat(req: ChatRequest) -> AsyncIterable[ServerSentEvent]:
    saving = asyncio.create_task(save_message(req.thread_id, "user", req.message))
    history = await get_conversation_context(req.thread_id)
    stream = await client.chat.completions.create(
        model=settings.chat_model,
        messages=history + [{"role": "user", "content": req.message}],
        stream=True,
    )
    parts = []
    async for chunk in stream:
        if chunk.choices and (token := chunk.choices[0].delta.content):
            parts.append(token)
            yield ServerSentEvent(data={"text": token}, event="token")
    await saving
    await save_message(req.thread_id, "assistant", "".join(parts))
    yield ServerSentEvent(raw_data="[DONE]", event="done")
FastAPI also sends a keep-alive ping every 15 seconds and sets X-Accel-Buffering: no, so proxies such as Nginx do not hold tokens back. Other levers for time to first token: reuse one HTTP client, keep the system prompt short, and run retrieval in parallel with loading history.
How do you manage chatbot memory across a conversation?
Give each conversation a thread_id, load its recent messages on every turn, and summarize the older ones once they pass a token budget. Context windows are large now, but every token you resend costs money and adds latency on every turn.
For short conversations, send everything. For long ones, keep the last messages verbatim and replace the rest with a stored summary.
# filename: app/memory.py
# description: Load recent messages for a thread, and summarize when they exceed the budget.
async def get_conversation_context(thread_id: str, max_tokens: int = 4000) -> list[dict]:
    rows = await db.fetch(
        """
        SELECT m.role, m.content
        FROM chat_messages m
        JOIN chat_sessions s ON s.id = m.session_id
        WHERE s.thread_id = $1
        ORDER BY m.created_at DESC
        LIMIT 20
        """,
        thread_id,
    )
    recent = [{"role": r["role"], "content": r["content"]} for r in reversed(rows)]
    if sum(count_tokens(m["content"]) for m in recent) <= max_tokens:
        return recent
    return await get_summarized_context(thread_id, recent)


async def get_summarized_context(thread_id: str, recent: list[dict]) -> list[dict]:
    summary = await db.fetchval(
        "SELECT summary FROM conversation_summaries WHERE thread_id = $1", thread_id
    )
    if not summary:
        summary = await summarize_messages(recent[:-10])  # one LLM call
        await db.execute(
            "INSERT INTO conversation_summaries (thread_id, summary) VALUES ($1, $2)",
            thread_id, summary,
        )
    return [{"role": "system", "content": f"Earlier in this conversation: {summary}"}, *recent[-10:]]
The window of 20 messages and the 4,000-token budget are example values. Tune them to your model’s price and your users’ conversation length. If you run LangGraph, its checkpointers store thread state for you, as in LangGraph persistence and thread models.
How does the chatbot decide when to use RAG or tools?
Let the model decide with tool calling. You describe each tool with a JSON schema. The model either answers directly or asks for a tool call, your code runs the tool, and the result goes back for the final answer.
This keeps “Thanks!” from triggering a vector search. It also lets “Where is my order?” call your order API instead of guessing.
# filename: app/tools.py
# description: One tool-calling round trip with the OpenAI Chat Completions format.
import json

tools = [{
    "type": "function",
    "function": {
        "name": "search_knowledge_base",
        "description": "Search company documentation",
        "parameters": {
            "type": "object",
            "properties": {"query": {"type": "string"}},
            "required": ["query"],
        },
    },
}]

async def answer(messages: list[dict]):
    first = await client.chat.completions.create(model=settings.chat_model, messages=messages, tools=tools)
    msg = first.choices[0].message
    if not msg.tool_calls:
        return msg.content
    messages.append(msg)
    for call in msg.tool_calls:
        args = json.loads(call.function.arguments)
        result = await TOOLS[call.function.name](**args)
        messages.append({"role": "tool", "tool_call_id": call.id, "content": json.dumps(result)})
    final = await client.chat.completions.create(model=settings.chat_model, messages=messages, tools=tools)
    return final.choices[0].message.content
Every tool result must carry the tool_call_id of the call it answers. Anthropic’s Messages API uses tool_use and tool_result content blocks for the same loop. The tool calling deep dive covers both formats.
How do you handle exceptions and outages in a chatbot?
Classify failures and give each class its own control. Abuse gets a rate limit, transient provider errors get a bounded retry, and a provider that keeps failing gets a circuit breaker with a fallback.
Rate limits per user
One user with a script can spend your monthly budget in an hour. Count requests per user in Redis, and count tokens too. Use the async Redis client so the check does not block the event loop.
# filename: app/limits.py
# description: Fixed-window request and token limits per user in Redis.
from datetime import date

import redis.asyncio as redis
from fastapi import HTTPException

r = redis.Redis()

async def check_rate_limit(user_id: str, limit: int = 50, window_s: int = 3600) -> None:
    key = f"rl:{user_id}"
    count = await r.incr(key)
    if count == 1:
        await r.expire(key, window_s)
    if count > limit:
        raise HTTPException(status_code=429, detail="Too many messages. Try again later.")

async def add_tokens(user_id: str, tokens: int, daily_budget: int = 100_000) -> bool:
    key = f"tokens:{user_id}:{date.today()}"
    total = await r.incrby(key, tokens)
    if total == tokens:
        await r.expire(key, 86_400)
    return total <= daily_budget
Circuit breakers and fallbacks
A circuit breaker stops calling a provider that keeps failing. After a set number of failures it opens and fails fast. After a reset timeout it lets one trial call through, and closes again if that call succeeds.

# filename: app/breaker.py
# description: Minimal async circuit breaker with a fallback provider.
import time

class CircuitOpen(Exception):
    pass

class CircuitBreaker:
    def __init__(self, failure_threshold: int = 3, reset_timeout: float = 60.0):
        self.failure_threshold = failure_threshold
        self.reset_timeout = reset_timeout
        self.failures = 0
        self.state = "closed"
        self.opened_at = 0.0

    async def call(self, fn, *args, **kwargs):
        if self.state == "open":
            if time.monotonic() - self.opened_at < self.reset_timeout:
                raise CircuitOpen()
            self.state = "half_open"
        try:
            result = await fn(*args, **kwargs)
        except Exception:
            self.failures += 1
            if self.state == "half_open" or self.failures >= self.failure_threshold:
                self.state, self.opened_at = "open", time.monotonic()
            raise
        self.state, self.failures = "closed", 0
        return result

primary = CircuitBreaker()

async def generate(messages):
    try:
        return await primary.call(call_primary_llm, messages)
    except Exception:
        return await call_fallback_llm(messages)  # or a friendly "try again in a minute"
Count only transient failures against the breaker. A 400 from a malformed prompt says nothing about the provider’s health. The LLM API retry patterns guide lists which status codes to retry and which to raise.
Slow work off the chat path
A user uploads a long PDF and asks about it. Parsing and embedding can take far longer than a chat turn, so run it in a task queue such as Celery (Python) or BullMQ (Node.js). Store progress per task, and stream status events to the chat while the worker runs.
# filename: app/ingest.py
# description: Document ingestion as a Celery task that reports progress.
from celery import Celery

celery_app = Celery("chatbot", broker="redis://localhost:6379/0")

@celery_app.task(bind=True)
def process_document(self, file_path: str, thread_id: str):
    self.update_state(state="PROGRESS", meta={"progress": 0})
    chunks = parse_pdf(file_path)
    self.update_state(state="PROGRESS", meta={"progress": 50})
    store_in_vector_db(embed(chunks), thread_id)
    return {"status": "complete", "chunks": len(chunks)}
How do you manage chatbot versions in production?
Treat the model ID and the system prompt as one versioned release. Pin an exact model ID in config, keep prompts in git with a version tag, and write both onto every assistant message.
- Pin the model. Use the provider’s dated or fixed model ID, not a moving alias, so behavior changes only when you change config.
- Version the prompt. A prompt edit is a code change: review it, tag it and deploy it like code.
- Gate on evals. Run a fixed set of real conversations against the new version before it ships.
- Roll out in steps. Route a share of users to the new version with a feature flag, and compare ratings, errors and cost.
- Keep rollback cheap. Because each message records
modelandprompt_version, you can find the bad answers and switch the flag back.
How do you see what a production chatbot is doing?
Trace every request. A trace records the user message, the retrieved documents, each LLM and tool call, timings, tokens and errors, all under one request ID. When a user reports a wrong answer, the trace shows whether retrieval or generation failed.
Start with structured logs keyed by request ID and per-step timings. Then move to a tracing tool such as Langfuse, LangSmith or Arize Phoenix. Alert on p95 time to first token, error rate and spend per user. The Langfuse and Grafana monitoring guide wires this up.
What to do next
- Make every handler async and switch to the async LLM and Redis clients.
- Stream replies over SSE and measure time to first token at p95.
- Store messages per
thread_idand add a token budget with summarization. - Add per-user request and token limits in Redis.
- Wrap each LLM provider in a circuit breaker with a fallback model or a clear error.
- Move document ingestion and other slow jobs to a task queue.
- Record
modelandprompt_versionon every assistant message, and trace every request.
Frequently asked questions
Should I use WebSockets or SSE for a production chatbot?
Use SSE for most chatbots. A chat reply flows one way, from server to client, and SSE carries it over a plain HTTP response that proxies and load balancers already handle. The LLM provider APIs stream with SSE too. Pick WebSockets when the client must send events during the stream, such as live voice audio or shared editing.
Why is my AI chatbot too slow in production?
Most slow chatbots wait for the full answer before sending anything. Stream tokens over SSE so the first words appear quickly. Then remove blocking work from the path to the first token: use async clients, save messages in the background, and load history and retrieval in parallel. Check that no proxy buffers the stream, and measure time to first token at p95.
What are best practices for managing exceptions in a chatbot?
Classify each failure before you act on it. Retry transient provider errors such as 429 and 5xx with backoff and a cap. Raise client errors such as 400 at once. Wrap each provider in a circuit breaker with a fallback model. Show users a short, friendly message, and keep model names, stack traces and tokens in your logs, never in the chat window.
Can you run an AI chatbot on premise?
Yes. The architecture stays the same, and only the AI layer changes. You replace the hosted LLM API with a model server on your own hardware. Many self-hosted servers, such as vLLM and Ollama, expose an OpenAI-compatible API, so the client code changes little. You then own GPU capacity, model updates and uptime, so budget for that operations work.
Which hosting handles streaming and long chatbot requests well?
Any host that allows long-lived HTTP responses and does not buffer them. Check three settings: the request timeout must exceed your longest generation, proxy buffering must be off, and HTTP/2 should be on. Serverless functions often cap request duration, so check that limit first. Containers behind a load balancer with a raised idle timeout work well for SSE.
Sources
- Server-Sent Events, FastAPI documentation, checked October 2026:
fastapi.sseadded in 0.135.0, SSE over POST, the 15-second keep-alive ping and theX-Accel-Bufferingheader. - Using server-sent events, MDN Web Docs, checked October 2026:
EventSourcereconnection and the six-connection limit per domain over HTTP/1. - useChat reference and stream protocols, Vercel AI SDK docs, checked October 2026: the
@ai-sdk/reactimport,sendMessage, messagepartsand the UI message stream format. - CircuitBreaker, Martin Fowler, March 2014: the closed, open and half-open states.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997