Newsletter, guides
Connection pooling for Python AI services
Manage database connections in a Python AI agent service: pool sizing, pre-ping, lifespan, PgBouncer, and why no connection is held while the LLM streams.
Your agent service is fine with 10 users. At 100, the logs fill with QueuePool limit of size 5 overflow 10 reached, connection timed out and server closed the connection unexpectedly. Postgres is healthy. The agent code is fine. The problem is how the service borrows and returns database connections while it waits on a model.
To manage database connections in a Python AI service, use one connection pool per worker process, created in the FastAPI lifespan. Turn on pool_pre_ping and set pool_recycle. Most important: borrow a connection only for the query, then give it back before the LLM call starts. An agent turn lasts seconds. A query lasts milliseconds. Size the pool for the queries, not the turn.
# filename: db.py
# description: One async engine per worker, sized for short checkouts.
from sqlalchemy.ext.asyncio import create_async_engine, async_sessionmaker

engine = create_async_engine(
    'postgresql+asyncpg://app:secret@db:5432/agents',
    pool_size=10,        # connections kept open per worker
    max_overflow=5,      # extra connections under a burst
    pool_timeout=10,     # fail fast instead of queueing for 30 s
    pool_pre_ping=True,  # test each connection on checkout
    pool_recycle=1800,   # replace connections older than 30 minutes
)
Session = async_sessionmaker(engine, expire_on_commit=False)
Key takeaways
- An agent request should hold a database connection for milliseconds, never for the seconds an LLM call takes. Read, return the connection, call the model, then borrow again to write.
- SQLAlchemy’s defaults are
pool_size=5,max_overflow=10andpool_timeout=30. Agent services usually need a faster timeout so a full pool fails loudly instead of hanging. pool_pre_ping=Truecatches connections that a firewall, load balancer or Postgres restart killed while they sat idle.pool_recycleretires them before that happens.- Every worker and every container has its own pool. Multiply
pool_size + max_overflowby all of them and keep the total under half of Postgresmax_connections(default 100). - Do not write every streamed token to Postgres. Buffer the reply in memory and save it once, or in a few checkpoints.
- Add PgBouncer when the connection budget no longer fits. With asyncpg behind transaction pooling, turn off or rename prepared statements.
Why do agent services run out of connections under load?
Because a naive agent route holds one connection for the whole turn. It opens a session, loads the chat history, calls the LLM, waits 5 to 30 seconds for the stream, runs a tool, waits again, and finally saves the reply. The connection does nothing for almost all of that time, but no other request can use it.
With pool_size=5 and max_overflow=10, a worker can serve 15 such turns at once. The 16th request waits up to pool_timeout seconds, then fails with the QueuePool limit error. A bigger pool only moves the wall, and it moves it into Postgres, which has a hard max_connections limit.
Idle connections cause the second error. A connection that sits in the pool for minutes can be closed by a NAT gateway, a cloud load balancer, a failover, or a Postgres idle_session_timeout someone set. The next request that checks it out gets a dead socket and a broken pipe or server closed the connection error.
How do you keep the connection off the LLM call?
Split the turn into short database steps around the model call. Each async with Session() block checks a connection out and returns it when the block ends, even on an exception or a cancelled request.
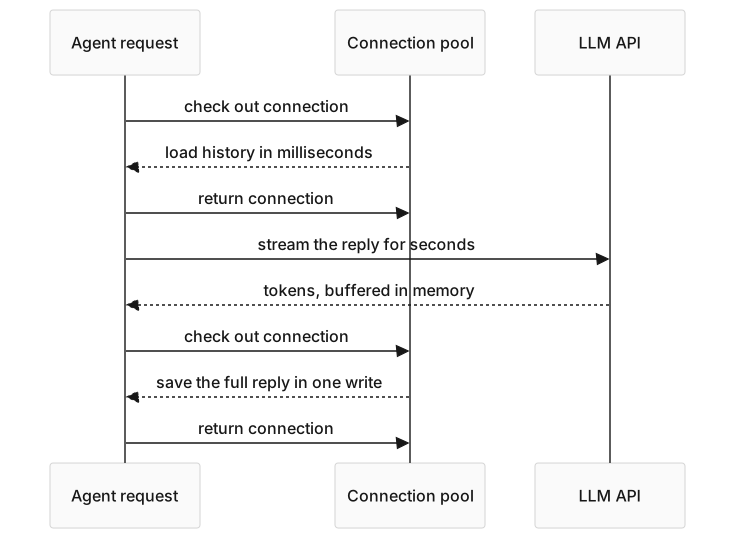
# filename: chat.py
# description: Short checkouts around a long LLM call.
from fastapi import FastAPI
from db import Session
from store import load_history, save_turn
from llm import stream_reply

app = FastAPI()


@app.post('/chat/{thread_id}')
async def chat(thread_id: str, message: str):
    async with Session() as s:           # connection out
        history = await load_history(s, thread_id)
    # connection back in the pool here

    parts = []
    async for token in stream_reply(history, message):  # seconds, no connection held
        parts.append(token)

    async with Session() as s, s.begin():  # connection out again
        await save_turn(s, thread_id, message, ''.join(parts))
    return {'reply': ''.join(parts)}
Tools follow the same rule. A tool that runs a SQL query opens its own short session inside the tool function. It does not reuse a session that the route opened before the model call.
This one change does more than any pool setting. A worker that held 15 connections for 15 slow turns now holds them for a few milliseconds each, so the same pool serves many more concurrent conversations.
Should you write every streamed token to Postgres?
No. Every UPDATE in Postgres writes a new row version, which adds WAL traffic and leaves dead rows for vacuum. A model streams tens of tokens per second. 100 open chats writing each token would ask Postgres for thousands of updates per second to build text nobody reads until the turn ends.
Buffer the reply in memory, as the route above does, and write it once when the stream ends. If you need to survive a crash or a reconnect mid-stream, checkpoint every second or every few hundred tokens, or keep the live stream in Redis and write only the final message to Postgres. The streaming guide shows the reconnect side of that buffer.
Which pool settings matter, and what should they be?
Five settings on create_async_engine do most of the work. SQLAlchemy uses AsyncAdaptedQueuePool for async engines, with the same options as QueuePool.
pool_size(default 5): connections kept open per worker. With short checkouts, 5 to 10 is usually enough.max_overflow(default 10): extra connections opened during a burst and closed when returned.pool_timeout(default 30 seconds): how long a request waits for a free connection. Drop it to 5 or 10, so a saturated pool shows up as fast errors in your metrics instead of slow requests.pool_pre_ping=True: runs a cheap ping on checkout and replaces a dead connection before your code sees it. SQLAlchemy’s docs note it does not save a connection that dies in the middle of a transaction, so keep transactions short and retry that case.pool_recycle(default off): retires connections older than this many seconds. Set it below the shortest idle timeout between you and the database, such as a load balancer’s.
If you use psycopg 3 directly instead of SQLAlchemy, psycopg_pool.AsyncConnectionPool covers the same ground with min_size, max_size, max_idle, max_lifetime and a check callback. Create it with open=False and await pool.open() in the lifespan, because opening an async pool in the constructor is deprecated.
How do you size the pool across workers and containers?
Count every pool that can reach the database. Each Uvicorn worker runs its own lifespan and opens its own pool. Each container runs its own workers.

Worked example: 2 containers, 4 workers each, pool_size=10 and max_overflow=5. The worst case is 2 x 4 x 15 = 120 connections, which is already past the Postgres default of 100. Halve the pool, cut workers, or put PgBouncer in front. Keep the budget under half of max_connections, because migrations, cron jobs, admin tools and other services also need connections.
Measure before you tune. Log engine.pool.status() or export checked-out connections as a metric. If checkouts sit near zero between requests, your pool is large enough. For wiring that metric, see Prometheus metrics for agent services.
How do you wire the pool into FastAPI with lifespan?
Build the engine inside the lifespan, so each worker creates its own pool after it starts, and dispose of it on shutdown so a deploy closes connections cleanly.
# filename: main.py
# description: One engine per worker, created and closed by the lifespan.
from contextlib import asynccontextmanager
from fastapi import FastAPI, Request
from sqlalchemy.ext.asyncio import create_async_engine, async_sessionmaker


@asynccontextmanager
async def lifespan(app: FastAPI):
    engine = create_async_engine(
        DATABASE_URL, pool_size=10, max_overflow=5,
        pool_timeout=10, pool_pre_ping=True, pool_recycle=1800,
    )
    app.state.Session = async_sessionmaker(engine, expire_on_commit=False)
    yield
    await engine.dispose()


app = FastAPI(lifespan=lifespan)


async def get_session(request: Request):
    async with request.app.state.Session() as session:
        yield session
Pooled connections must never cross a process fork. If something forks after the engine exists, such as Gunicorn with --preload or a multiprocessing pool, SQLAlchemy’s docs say to call engine.dispose(close=False) in the child so it starts with fresh connections. Creating the engine in the lifespan avoids the problem.
Use the get_session dependency only for routes that finish in milliseconds. For agent routes, open short sessions inside the handler as shown earlier, so the dependency does not hold a connection for the whole stream. The FastAPI and Uvicorn guide covers the rest of the lifespan setup.
Why does the pool leak connections until the service dies?
Because some code path checks a connection out and never returns it. The symptom is a pool that works for hours, then fills with QueuePool limit reached errors until a restart. Three bugs cause most leaks in async Python:
- A session opened without
async with.session = Session()followed by an exception beforeawait session.close()leaves the connection checked out. - Swallowing
asyncio.CancelledError. When a client disconnects, the server cancels the task. Catching the cancel and returning a value stops cleanup in outer context managers. Re-raise it. - A long transaction around a slow call.
async with s.begin():wrapped around an LLM or HTTP call holds a connection and an open transaction for seconds, and also blocks vacuum.
Fix all three the same way: every checkout lives in an async with block that wraps only database work.
When should you add PgBouncer?
When the connection budget no longer fits under max_connections, usually when you scale to many containers. PgBouncer sits between the app and Postgres and shares a small set of server connections among many client connections. In transaction mode, a client holds a server connection only for the length of a transaction.
Transaction mode has one well-known catch with asyncpg. asyncpg prepares statements by default, and its FAQ says PgBouncer in transaction or statement mode does not support that. Two fixes:
- Turn off asyncpg’s statement cache. With SQLAlchemy, add
prepared_statement_cache_size=0to the URL and passconnect_args={'statement_cache_size': 0}. - Or use PgBouncer’s
max_prepared_statementssetting (default 200 in current releases), which tracks protocol level prepared statements in transaction mode. Check your PgBouncer version and test before you rely on it.
If the database is small and one or two containers talk to it, skip PgBouncer. It is another moving part to run and monitor.
What to do next
- Search your agent routes for a session or connection that stays open across an LLM call. Split it into short
async withblocks before and after. - Add
pool_pre_ping=Trueand apool_recyclebelow your shortest network idle timeout. - Lower
pool_timeoutto 5 or 10 seconds and alert on pool timeout errors. - Compute containers x workers x (
pool_size+max_overflow) and keep it under half ofmax_connections. - Buffer streamed replies in memory and write them once, not per token.
- Load test at twice your expected peak for 30 minutes and watch checked-out connections and Postgres connection counts.
Frequently asked questions
How many database connections does a FastAPI AI agent need?
Far fewer than concurrent users, if each request returns its connection before the LLM call. Queries take milliseconds and LLM calls take seconds, so a pool of 5 to 10 per worker serves many concurrent chats. Check the total across all workers and containers against Postgres max_connections and keep it under half.
What causes broken pipe errors in SQLAlchemy?
A pooled connection was closed by something outside the app while it sat idle, such as a NAT gateway, load balancer, failover or Postgres idle timeout. The next checkout gets the dead socket. pool_pre_ping=True detects it on checkout and replaces it, and pool_recycle retires connections before they get old enough to be cut.
Should I use asyncpg or psycopg 3 for an async AI service?
Both are solid async Postgres drivers and both work with SQLAlchemy’s async engine. asyncpg is a long-standing choice for raw speed. psycopg 3 has a maintained pool package, psycopg_pool, and is the driver many teams already know from psycopg2. Pick one, keep the pool settings in one place, and measure with your own queries.
Can I stream LLM tokens straight into Postgres?
You can, but you should not write one row update per token. Each update creates a new row version and WAL traffic. Buffer the reply in memory and save it at the end, checkpoint every second or few hundred tokens, or keep the live stream in Redis and store only the final message.
Do I need PgBouncer for an AI agent service?
Not at first. Add it when containers x workers x pool size approaches Postgres max_connections. With asyncpg behind PgBouncer in transaction mode, disable prepared statement caching or use PgBouncer’s prepared statement tracking.
Sources
- Connection Pooling, SQLAlchemy 2.0 documentation, release 2.0.55, October 2026:
QueuePooldefaults, pre-ping limits,pool_recycle, and pools across forked processes. - Connection pools, psycopg 3.3 documentation, October 2026:
AsyncConnectionPoolsizing,check, and the deprecated open in constructor. - Frequently Asked Questions, asyncpg documentation, accessed October 2026: PgBouncer transaction mode and
statement_cache_size=0. - PgBouncer configuration, PgBouncer documentation, accessed October 2026:
pool_mode,default_pool_sizeandmax_prepared_statements. - Connections and Authentication, PostgreSQL 18 documentation, accessed October 2026:
max_connectionsdefault of 100.
Build what you just read, with Param, live
You read the guide
- Free Live LabBuild a Second Brain with Claude CodeA second brain over your notes, docs and Linear that answers with sources and serves the same memory to any agent over MCP.Free seat
- ProWatch the video coursesDesign a Software Factory for Your Coding Agents, Build Your First Software Factory Execution Harness and each new course as the sessions are cut. The first lesson of each is free after you sign in.$149 a year
- WorkshopAI Agents in Production for EngineersA multi-agent system deployed with an identity per agent, permissions, guardrails, an LLM gateway, traces and evals, plus a checklist for your own agents.$497
- BuildcampAgentic AI Buildcamp for Engineers & PMsDesign, build and deploy a production agentic AI system in four weeks$997